In the rapidly evolving landscape of artificial intelligence and software development, a persistent confusion surrounds two terms that are frequently used interchangeably: prompt engineering and prompt optimization. Industry expert and software engineer Shittu Olumide recently addressed this semantic overlap, drawing a clear distinction between designing a prompt from scratch and refining an existing one through structural enhancements, specificity, and iteration without altering the underlying model itself.
According to Olumide, this distinction is critical for developers and practitioners who are constantly seeking to optimize large language model outputs. Most professionals asking how to improve their results already possess a functional prompt. Rather than requiring a blank-page framework, they need targeted, evidence-backed modifications that demonstrably move the needle, moving away from subjective adjustments and toward reliable, measurable outcomes.
To illustrate these principles, Olumide applied five concrete optimization strategies to a single, deliberately complex test case: a raw, multi-speaker meeting transcript laden with conversational ambiguities. The transcript details a three-person discussion concerning a checkout redesign, a billing service migration, support queue triage, and tablet breakpoint reviews.
The complexity of the text lies in three specific challenges: a mobile review assignment that shifts mid-conversation from one participant to another, a tablet-breakpoint check that is folded into the existing review rather than spun off into a separate task, and an unassigned support-queue triage owner that is deliberately left unresolved rather than guessed or dropped. Olumide noted that a prompt capable of capturing only the straightforward elements of such a conversation fails in a production environment, underscoring the necessity of robust optimization strategies.
Specifying Structured Output
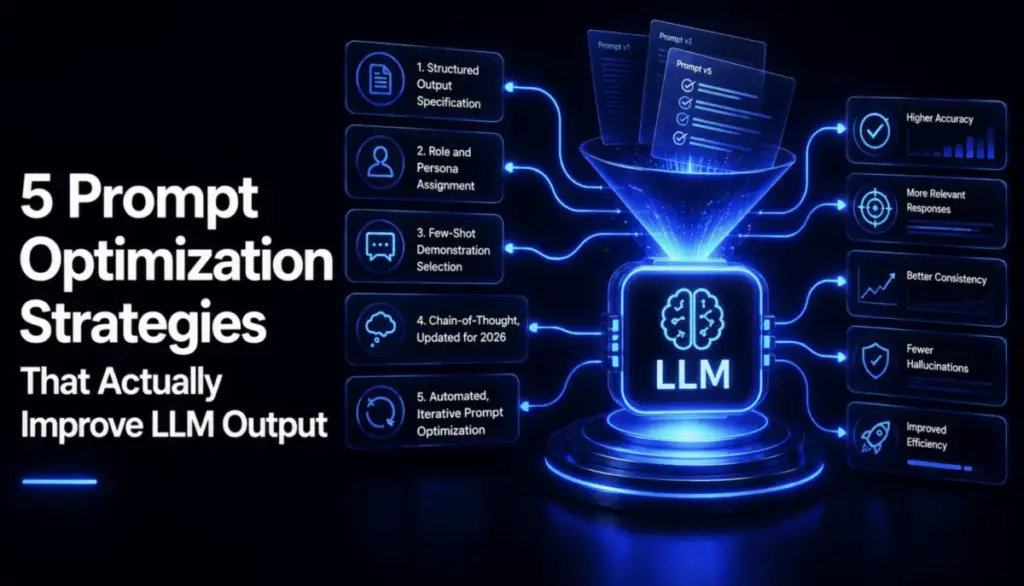
The first and most immediately measurable lever in prompt refinement involves moving away from unstructured prose and demanding structured output. While asking a model to list action items in plain text yields a readable response, it fails to produce data that downstream systems can reliably parse. In a production setting, unparseable output represents a critical failure rather than a minor inconvenience.
By implementing strict schema validation using tools like Pydantic, developers can enforce rigorous data contracts. When tested against realistic outputs, vague prompt styles that returned numbered prose consistently failed programmatic validation. Conversely, requesting output framed within an explicit schema parsed cleanly into validated objects. This distinction bridges the gap between text that merely looks plausible to a human reader and data that a software application can process without manual intervention.
Assigning a Role and Persona
The second strategy involves assigning a specific role and persona to the model, a technique that activates relevant segments of its training data to yield more context-aware results. Generic instructions lack the targeted focus required to catch conversational nuances.
By framing the model as a meticulous executive assistant familiar with the ambiguities of corporate meetings—such as mid-sentence changes of mind and unconfirmed assignments—the prompt primes the system to watch for specific pitfalls before it begins processing the text. This contextual priming proves invaluable when analyzing messy transcripts where a casual first pass would easily overlook crucial corrections.
Selecting Few-Shot Demonstrations
Research into prompt optimization indicates that the selection of few-shot demonstrations often exerts a greater impact on output quality than the phrasing of instructions alone. Crucially, the effectiveness of few-shot learning hinges not merely on adding examples, but on selecting diverse cases that cover distinct patterns rather than near-duplicates.
Olumide highlighted the use of diversity-aware algorithms, such as those employing TF-IDF vectorization and cosine similarity, to filter out redundant examples from a candidate pool. By ensuring that a few-shot set incorporates genuinely different scenarios—such as a confirmed owner, an unresolved owner, and a merged task—developers provide the model with a comprehensive framework for handling varied conversational structures rather than repeatedly teaching the same basic pattern.
Prompting for Chain-of-Thought
Chain-of-thought prompting, which encourages models to reason step by step before answering, continues to serve a vital purpose, particularly when handling complex ambiguities. While frontier models now possess native reasoning capabilities that reduce the necessity of explicit step-by-step instructions for straightforward tasks, ambiguous scenarios still benefit significantly from structured reasoning.
For instance, without prompted reasoning, a model processing the sample transcript might latch onto the initial assignment of the mobile review and miss the subsequent correction made later in the conversation. By instructing the model to trace ownership across the entire dialogue before finalizing its extraction, the prompt forces the system to evaluate the complete exchange rather than pattern-matching on the first plausible assignment. For cost-conscious applications, variations like Chain of Draft allow models to maintain reasoning accuracy while drastically reducing token consumption.
Running Automated, Iterative Prompt Optimization
The most advanced strategy detailed in Olumide’s analysis shifts prompt refinement from intuitive guesswork to an automated, measurable search process. Rather than relying on manual adjustments, developers can score candidate prompt fragments against real test cases using automated hill-climbing algorithms.
In practical demonstrations, starting from a bare instruction and iteratively testing candidate fragments—such as rules for handling reassigned owners or unassigned tasks—allowed an automated search to discover the minimum effective set of instructions. This iterative approach achieved a perfect score by identifying precisely the corrections required for the dataset, avoiding the inclusion of superfluous instructions.
Ultimately, these five methodologies converge on a single underlying discipline: replacing intuition with empirical testing against real-world test cases. Whether addressing parsing failures through structured schemas, resolving conversational drift through targeted demonstrations, or uncovering optimal instructions via automated search, developers can build robust, production-ready prompts grounded in verifiable performance rather than speculation.
Shittu Olumide is a software engineer and technical writer recognized for simplifying complex technological concepts. Additional insights and professional updates from Olumide can be found via LinkedIn and Twitter.