





 Standard
Leveraging Large Language Models for Advanced Named Entity Recognition Without Custom Training
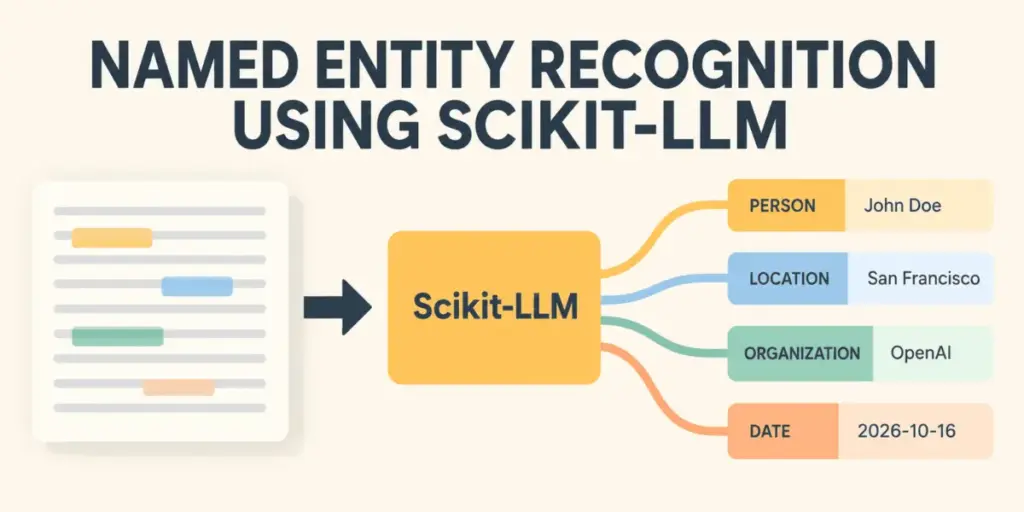
The process of turning messy, unstructured text into organized, actionable data remains one of the most persistent hurdles in modern data analysis and machine learning. Traditionally, extracting structured information—such as company names, executive titles, hardware products, and geographical locations—required extensive natural language processing libraries. These legacy systems typically demanded massive training datasets and grueling fine-tuning…