 Standard
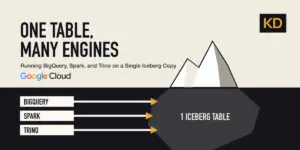
Google Cloud’s Borderless Lakehouse and Apache Iceberg Unite BigQuery, Spark, and Trino on a Single Data Copy
In the traditional architecture of modern data engineering, organizations frequently fall into a pattern of data duplication. A standard configuration might deploy Google Cloud’s BigQuery for business analytics, Apache Spark for heavy-duty data pipelines, and Trino for the ad-hoc analytical queries that land late on a Friday afternoon. To make this multi-engine setup function, each…