 Standard
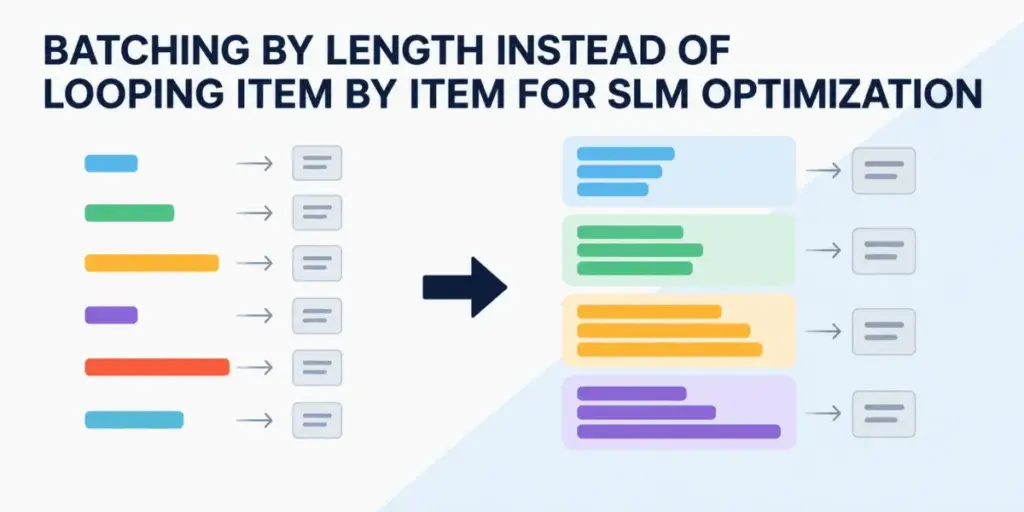
Optimizing Small Language Models: Boosting Inference Throughput with Length-Bucketed Batching
As artificial intelligence deployment shifts increasingly toward edge devices and local hardware, engineering teams are finding that raw model capability is only half the battle. Efficient execution matters just as much, particularly when deploying small language models (SLMs) for narrow, high-frequency automation tasks. In the final installment of a technical series examining performance optimization for…