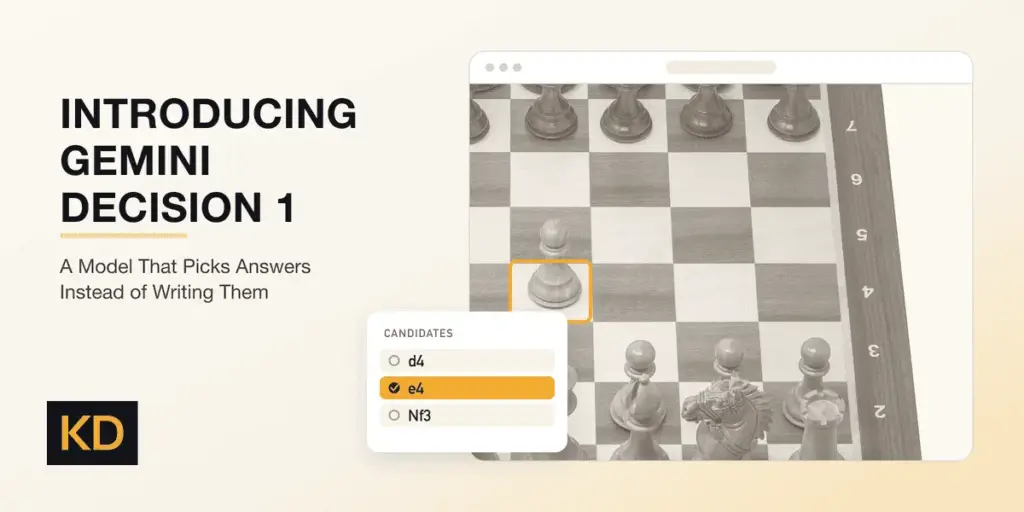
Google has launched a specialized artificial intelligence model designed to perform a single, focused function without generating conversational text. The new model, known as Gemini Decision 1, was introduced alongside the Gemini Decisions API. Rather than writing paragraphs, code, or structured responses, the system takes an input payload and a set of closed-ended questions, returning probabilistic evaluations such as binary yes-or-no answers, categorical selections, or numerical rubric scores.
While this approach may appear narrow at first glance, it addresses a widespread inefficiency in modern automated agent architectures. Contemporary artificial intelligence systems typically rely on dozens of background evaluation calls for routine operational tasks, such as determining which model should process a specific user query, selecting an appropriate computational tool, or verifying whether an incoming message violates content policies. Most development teams have historically handled these classification tasks by deploying full generative models paired with custom JSON parsers, effectively paying for output tokens that are ultimately discarded. Google is now commercializing this routing and decision-making layer independently, pricing the service at ten cents per million input tokens while charging nothing for output tokens because the model does not produce prose.
Gemini Decision 1 is built to process complex multimodal data in a single forward pass, accepting text, images, video, audio, and PDF documents up to 262,144 input tokens per request. Against this unified input, developers can pose up to 1,000 independent questions per call, covering boolean evaluations, categorical choices, and numerical scorings. Crucially, every returned answer is accompanied by a confidence metric, allowing programmatic workflows to route uncertain evaluations to human reviewers or fallback procedures.
The economic model centers on input-only billing at ten cents per million tokens, with shared inputs billed only once regardless of the number of evaluated questions. Google provides a no-cost prototyping tier through Google AI Studio. According to the platform’s capability documentation, the model deliberately excludes text generation, open-ended reasoning, function calling, structured output generation, batch processing, and prompt caching. It functions strictly as an analytical scoring engine rather than a general-purpose conversational chatbot.
Independent testing using the official Python software development kit and API keys from Google AI Studio reveals how the system performs across various inputs. Basic customer support routing tests involving text messages yield immediate categorical choices alongside near-certainty confidence ratings and rapid response latencies. When presented with ambiguous support messages that could plausibly fit multiple internal operational queues, the model declines to manufacture false certainty. Instead, it distributes probability scores across competing categories while simultaneously scoring specific attributes, such as product damage, with high confidence.
When processing multimodal inputs combining images and text, the model successfully extracts relevant details, such as identifying a spill, recommending appropriate remedial actions, and assigning a severity score. However, practical testing indicates that latency for multimodal queries is noticeably higher than baseline text-only operations, influenced by the retrieval of media assets from remote URLs and the processing of larger token counts. While initial text queries return rapidly, image-based requests require significantly more time, underscoring the importance of empirical benchmarking before deploying the model into latency-sensitive production environments.
Adoption of the Decisions API is already underway within Google’s internal ecosystem, where the technology powers classification and routing features across several company products. Industry observers and engineering teams evaluating the new tool have highlighted several key considerations regarding its practical deployment.
Foremost among these is the critical importance of utilizing the confidence score rather than relying solely on the primary categorical choice. Because classification models can encounter ambiguous inputs that divide probabilities evenly between options, relying strictly on the winning choice without evaluating its confidence margin can lead to misrouted workflows. Production systems must implement strict threshold checks to intercept low-confidence decisions and redirect them appropriately.
Furthermore, engineering teams must carefully measure latency within their own application environments, particularly when handling multimodal media payloads. While baseline metrics provided by infrastructure providers offer a general guideline, network round trips, media fetching overhead, and larger input contexts can introduce variability that must be accounted for in real-time user experiences. Additionally, developers migrating from existing fine-tuned classifiers should conduct direct comparative benchmarking to determine whether the platform’s pricing and accuracy profiles match their specific operational requirements.
As the ecosystem expands, Gemini Decision 1 is becoming accessible across major developer toolkits and integration platforms, including OpenRouter, LangChain, Vercel’s AI SDK, and LiteLLM, though native Google Cloud support remains slated for future release. For software engineering teams building automated agent stacks and policy enforcement pipelines, the model offers a streamlined, cost-effective mechanism for handling high-volume classification and routing tasks, provided that application logic is properly structured to interpret probabilistic confidence metrics alongside categorical selections.