In the rapidly evolving landscape of modern software engineering, the rise of artificial intelligence has triggered a wave of "hot takes"—those brief, punchy, and often inflammatory assertions that dominate social media feeds and technical forums. While these one-liners are masterclasses in driving engagement, they often prioritize sensationalism over genuine understanding. By distilling complex, nuanced engineering challenges into single, confident sentences, the industry risks losing sight of the deeper, more practical realities of building software in an AI-augmented world.
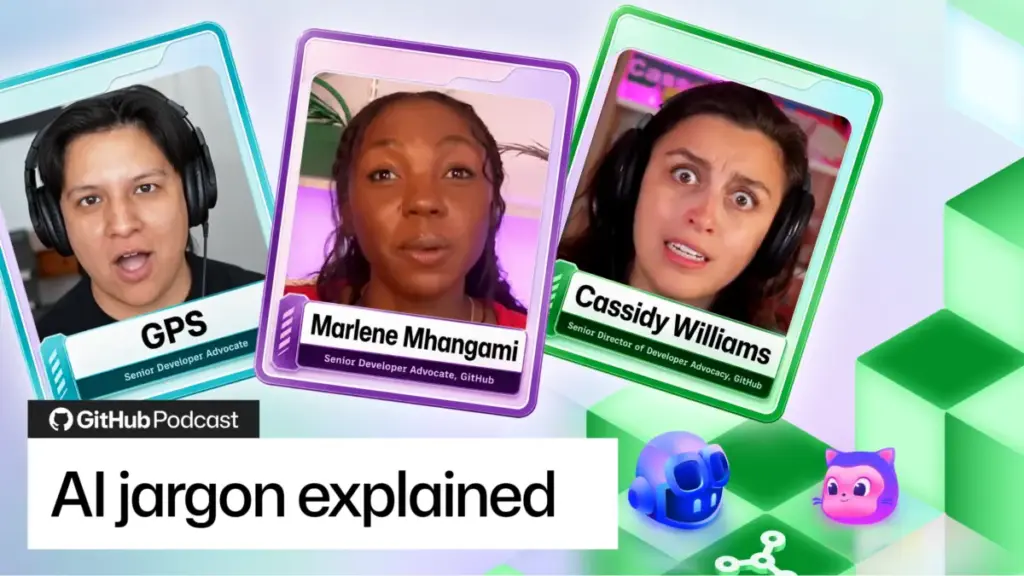
The true value of these provocative statements, however, is not found in the initial reaction they elicit. Instead, their worth lies in the process of deconstruction: questioning the underlying assumptions, identifying missing context, and exploring how these ideas hold up when applied to the rigors of professional software development. To help navigate this noise, the latest episode of the GitHub Podcast digs deep into these common AI narratives, moving past the surface-level rhetoric to uncover the practical, actionable insights hidden underneath.
Debunking the Myth of Passive Code Review
One of the most persistent hot takes currently circulating is the claim that developers no longer need to read code generated by AI. This sentiment, while perhaps born from a desire for efficiency, is fundamentally flawed. Even when an agent writes the syntax, the developer remains the ultimate steward of that code. Responsibility cannot be delegated to an algorithm.
However, the reality of code review in an AI-enabled workflow is more nuanced than a simple "read every line" mandate. Modern development requires a risk-based approach. A critical authentication refactor in a production system necessitates a drastically different level of scrutiny compared to a quick, low-stakes CSS experiment. Similarly, a developer’s instincts are shaped by their familiarity with a codebase; a system maintained for a decade warrants a different observational lens than a project initiated only that morning. Pretending that every line of code carries an identical level of risk is not a mark of rigor; it is simply an inefficient use of a developer’s limited time.
The most effective rule is to review until you possess the clarity to explain and own the outcome. Sometimes, this rigor begins before the AI even starts typing. By mapping dependencies, identifying potential edge cases, and establishing a clear architectural plan beforehand, a developer ensures they understand the "what" and the "why" before the code exists. At other times, the generated output demands the lion’s share of the attention, requiring a deep dive into error handling, security protocols, and performance metrics. Ultimately, AI shifts where the cognitive effort is applied, but it does not eliminate the need for intellectual labor. The mark of a skilled developer is now the ability to identify where the true risks reside.
AI Fluency as a New Professional Standard
Another common debate centers on the professional implications of AI adoption, with some claiming that companies will soon refuse to hire developers who do not integrate AI into their daily workflows. While this perspective is an oversimplification, it captures a shift in hiring expectations. It is increasingly common for interviewers to ask candidates how they utilize AI, as these tools are rapidly becoming foundational to the software development lifecycle.
Yet, there is no industry consensus suggesting that every developer must follow a specific, rigid workflow or mirror the same level of AI enthusiasm. The more valuable signal to employers is professional judgment. A candidate’s ability to articulate when they use AI versus when they choose to work manually is a sign of maturity. Employers are looking for engineers who can discuss the impact of AI on speed, quality, security, and long-term maintainability with honesty and nuance.
Total reliance on AI is just as problematic as a total refusal to use it. The ideal candidate is someone who demonstrates fluency—someone who understands what they can trust the tools to handle and where they must maintain active, manual oversight. This level of technical literacy is fast becoming a standard requirement for the modern craft of software engineering.
Resolving the Conflict Between Standards and Expertise
Technical debates often manifest as false dichotomies, such as the claim that "skills" have rendered the Model Context Protocol (MCP) obsolete. This is a misunderstanding of how these systems function. MCP and skills are not competing technologies; they are complementary components that solve different, equally important problems.

The Model Context Protocol provides a standardized interface for agents to connect with tools and data, ensuring that disparate systems can communicate reliably. It is about the "how" of interaction. Skills, conversely, represent packaged expertise—they encode the "why" and the "when." A skill might encapsulate a team’s preferred architectural patterns, project conventions, or best practices for using a specific tool. Because these skills are frequently documented in human-readable formats like Markdown, they serve a dual purpose: guiding both the AI and the developer. By using standards for shared interfaces and skills for context and process, developers can create a more robust and flexible ecosystem.
Why RAG is Still Relevant
Similarly, the declaration that Retrieval-Augmented Generation (RAG) is "dead" ignores its essential role in grounding AI systems. RAG is not an obsolete trend; it is a fundamental architectural pattern. By providing an AI with relevant, external information—such as internal documentation, support histories, or specific codebase context—developers enable the model to work with grounding rather than relying solely on its internal, training-based knowledge.
Without effective retrieval, a model is forced to rely on what it already knows or expend unnecessary computational resources searching for context. This increases token usage, slows down performance, and elevates the risk of incomplete or inaccurate outputs. Good retrieval narrows the search space, ensuring that the AI’s response is anchored in the information that actually matters. In a professional environment, agents, skills, MCP, and RAG are not fighting for dominance; they are distinct tools that, when integrated correctly, form a cohesive and effective development workflow.
The Maintainability Pressure Test
Finally, the notion that needing to fine-tune a model for a specific codebase is an indictment of that code’s quality is a useful, if harsh, provocation. While there are legitimate technical reasons to pursue fine-tuning, the fact remains that modern models are trained on vast repositories of code, frameworks, and architectural patterns. If a state-of-the-art model struggles to interpret a codebase, it is highly likely that a new human developer would face the same hurdles.
AI-assisted development acts as a stress test for maintainability. It reinforces the importance of clear structures, consistent naming conventions, and readable tests. When a codebase is designed to make its intent obvious, it becomes easier for both humans and AI to understand, debug, and extend. This is a positive evolution for the industry, as it rewards the kind of disciplined engineering that benefits everyone involved in the software’s lifecycle.
Prioritizing Real Work Over Abstract Debate
The rapid pace of AI development ensures that strong opinions will continue to surface. However, the most productive response to a provocative take is not to engage in a counter-debate, but to test the idea through practical application. Building, experimenting, and documenting results provides the community with evidence and valuable data points.
Projects like Pollinations AI, which explores incentive structures for open-source contributions in an AI-driven environment, and the "Avian Visitors" project—a creative, multi-hardware build log for a bird-listening e-ink display—demonstrate the value of moving beyond theory. These efforts do not claim to settle every debate, but they provide a foundation of reality, exposing the trade-offs and practical challenges that can only be discovered through actual construction.
The path forward for developers is clear: read enough code to maintain ownership of the result, build enough fluency to explain your process, and use tools like MCP and RAG to create grounded, efficient systems. When code is confusing, treat it as a maintainability problem rather than a mystery. Ultimately, the most important step is to take what is learned and apply it to the work itself. For those looking to stay informed on these evolving workflows and technical best practices, the GitHub Podcast continues to serve as a resource for navigating the intersection of human expertise and artificial intelligence.