 Standard
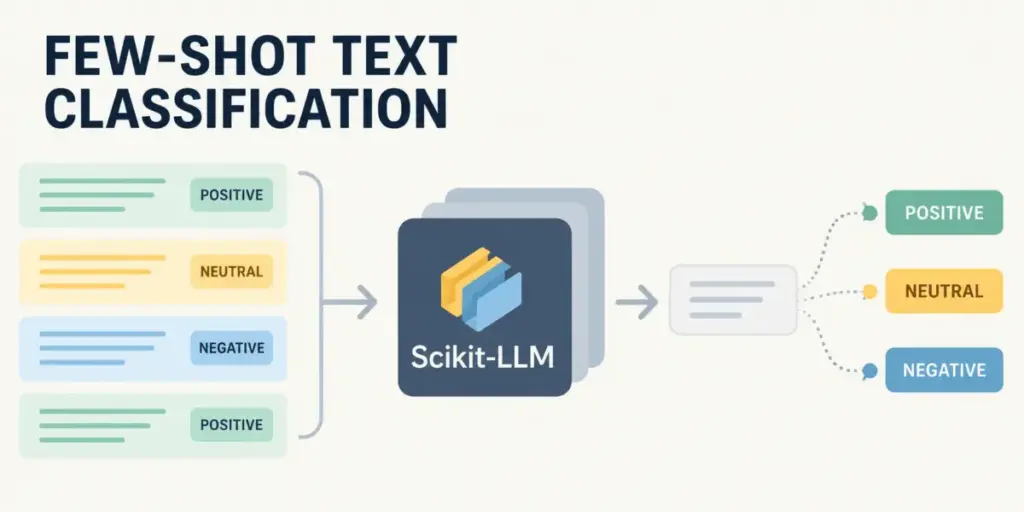
Bridging Traditional Machine Learning and Large Language Models: An Introduction to Scikit-LLM for Few-Shot Text Classification
For data scientists and machine learning engineers who have spent years building and refining text classification models, the workflow has long followed a familiar and rigorous path. Traditionally, developing a reliable classifier required collecting hundreds or even thousands of meticulously labeled examples, scrubbing raw text of noise and inconsistencies, converting unstructured data into numerical representations…