







Amazon Web Services has officially announced the general availability of AWS Glue 6.0, a significant update to its serverless data integration service that brings substantial cost optimizations and a modernized architectural foundation to the platform. By delivering a 30% reduction in pricing compared to previous versions, AWS is positioning the new release as a pivotal step in making large-scale data engineering more accessible and cost-effective for organizations managing growing data lakes and complex ETL pipelines.
Beyond the financial benefits, the release of AWS Glue 6.0 introduces comprehensive support for Apache Iceberg v3, reinforcing the platform’s commitment to open-table formats. Built on a modernized runtime that features Apache Spark 4.1, Python 3.13, and Scala 2.13, the update is engineered to deliver enhanced performance and improved developer productivity. This transition to a newer, more efficient engine stack is designed to streamline the handling of massive datasets while providing developers with the modern tools necessary for sophisticated data transformation tasks.
Modernizing the Data Integration Runtime
The core of the AWS Glue 6.0 value proposition lies in its foundational upgrade. By moving to Apache Spark 4.1, the service benefits from the latest advancements in the open-source community’s most popular distributed processing engine. This shift is not merely an incremental update; it represents a fundamental modernization that allows Glue to handle complex ETL workloads with greater speed and efficiency. The inclusion of Python 3.13 and Scala 2.13 ensures that data engineers have access to the most current language features, libraries, and security enhancements, facilitating better performance for PySpark applications and allowing for more elegant code structures.
This architectural shift is particularly timely as organizations continue to struggle with the complexities of managing semi-structured data at scale. With the integration of the full Apache Iceberg v3 specification, AWS Glue 6.0 provides what is arguably the most complete Iceberg implementation currently available on any fully serverless managed Spark service. This depth of integration allows users to leverage advanced features that were previously difficult to implement, particularly regarding the way data is read, stored, and managed within a data lake environment.
Revolutionizing Semi-Structured Data with VARIANT Support
One of the most anticipated features in this release is the support for the VARIANT data type, coupled with advanced shredding capabilities. In traditional data processing workflows, dealing with JSON, logs, and event-based data often required expensive and brittle schema-flattening processes. These processes frequently led to data duplication, complicated custom parsing logic, and, inevitably, pipeline breakages whenever a source schema underwent even minor modifications.
The VARIANT data type in AWS Glue 6.0 changes this paradigm entirely. By utilizing shredding support, the service can store and query semi-structured data without the need to force it into a rigid, flattened schema. This results in significantly faster query read performance, as the engine can navigate the data structures more effectively than it could with traditional string-based columns. For data teams, this means that the ingestion of raw, nested data—such as high-velocity telemetry or application logs—becomes much more resilient. The ability to handle evolving schemas without constant maintenance of ETL jobs allows teams to focus on generating insights rather than performing tedious data normalization.
Performance and Real-Time Capabilities
The modernization of the engine in AWS Glue 6.0 extends beyond just data format handling. The service has been tuned to deliver improved performance for PySpark applications, which serve as the backbone for many modern data pipelines. By optimizing the underlying execution environment, AWS has enabled developers to process larger volumes of data within the same or shorter timeframes.
Furthermore, the release introduces refined capabilities for real-time streaming, enabling processing with single-digit millisecond latency. This is a critical advancement for enterprises that rely on immediate insights for operational decision-making, such as fraud detection, real-time analytics, or personalized customer experiences. By reducing the overhead associated with streaming ingest, Glue 6.0 ensures that data freshness is no longer a bottleneck for time-sensitive applications. These improvements, combined with the overall reduction in pricing, provide a compelling argument for organizations to migrate their existing workloads to the latest version of the service.
Seamless Migration and Operational Ease
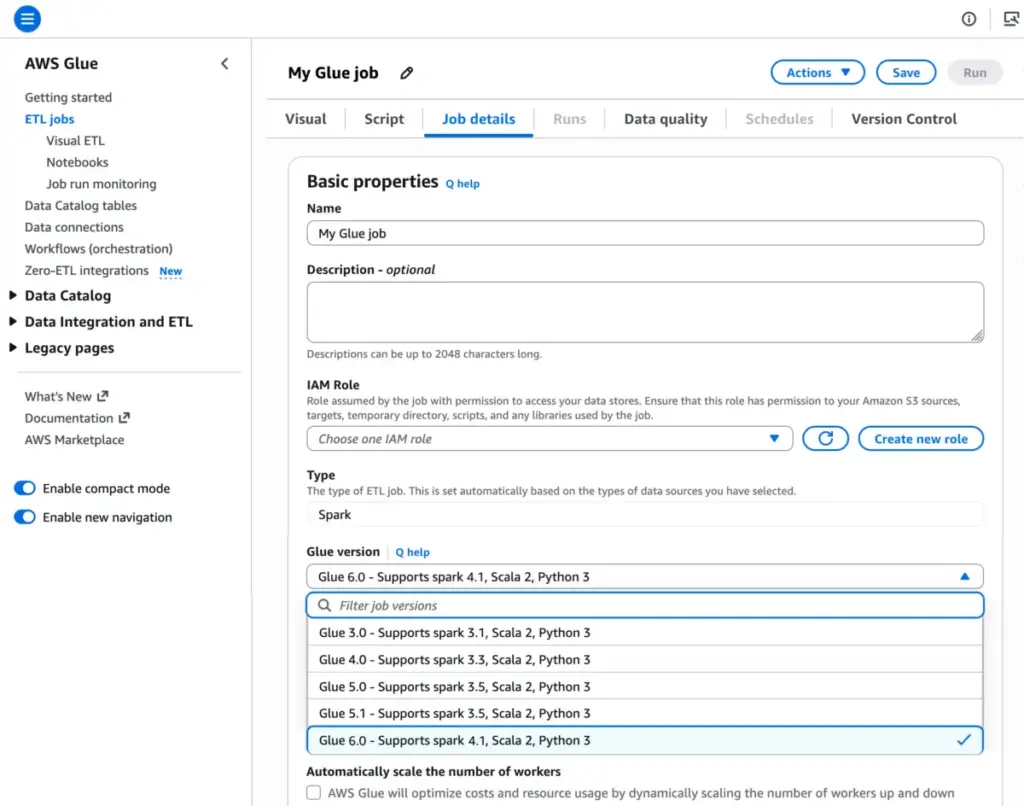
AWS has designed the transition to Glue 6.0 to be as frictionless as possible. In line with the company’s focus on developer experience, no API changes are required to adopt the new version. Existing jobs can be upgraded by simply selecting the new version parameter through the AWS Command Line Interface (CLI), the AWS SDK, or via the AWS Glue Studio interface. The flexibility offered by this approach allows teams to test their workloads against the new runtime in a non-disruptive manner before committing to a full-scale migration.
For users working within the AWS Glue Studio console, the process is straightforward: upon opening an existing job, the user can navigate to the "Job Details" tab and select "Glue 6.0" from the version menu. This option immediately unlocks access to the latest Spark, Python, and Scala versions, alongside the full suite of Iceberg v3 capabilities. For those who prefer working in interactive environments, Glue 6.0 is fully supported in Glue Studio notebooks and Jupyter notebooks through the use of the %glue_version magic command.

Recognizing the complexity of enterprise environments, AWS has also provided tools to assist in the transition, such as the Spark upgrade agent in Glue Studio. This utility helps identify potential compatibility issues, and the auto-upgrade feature allows for the streamlined migration of jobs, reducing the manual effort typically associated with moving to a major version update. Documentation detailing the release notes and specific migration paths is readily available to assist teams in ensuring their pipelines are optimized for the new environment.
Availability and Economic Impact
AWS Glue 6.0 is available today across all AWS regions where the service is operational. This broad rollout ensures that organizations globally can begin taking advantage of the performance gains and cost savings immediately. To stay informed about regional availability or to plan for future infrastructure deployments, users are encouraged to consult the AWS Capabilities by Region documentation.
For those who rely on automation and AI-assisted workflows, the integration with the AWS MCP Server and various plugins provides a sophisticated way to manage these new capabilities. Data engineers can query documentation, check for regional availability, or troubleshoot job issues directly through their preferred AI tools, further accelerating the development lifecycle.
The economic model remains consistent with the existing AWS Glue pricing structure, which is designed to be predictable and scalable. Users continue to pay an hourly rate, billed by the second, for crawlers and ETL jobs, while the AWS Glue Data Catalog remains subject to a simplified monthly fee for storage and access. Given that the first million objects and the first million accesses are free of charge, the price reduction for compute resources makes Glue 6.0 an even more attractive entry point for businesses looking to scale their data integration efforts without incurring prohibitive overhead. By lowering the cost of compute while simultaneously increasing the capabilities of the engine, AWS is effectively enabling higher data-processing throughput for the same investment, empowering teams to tackle larger and more complex analytics projects.