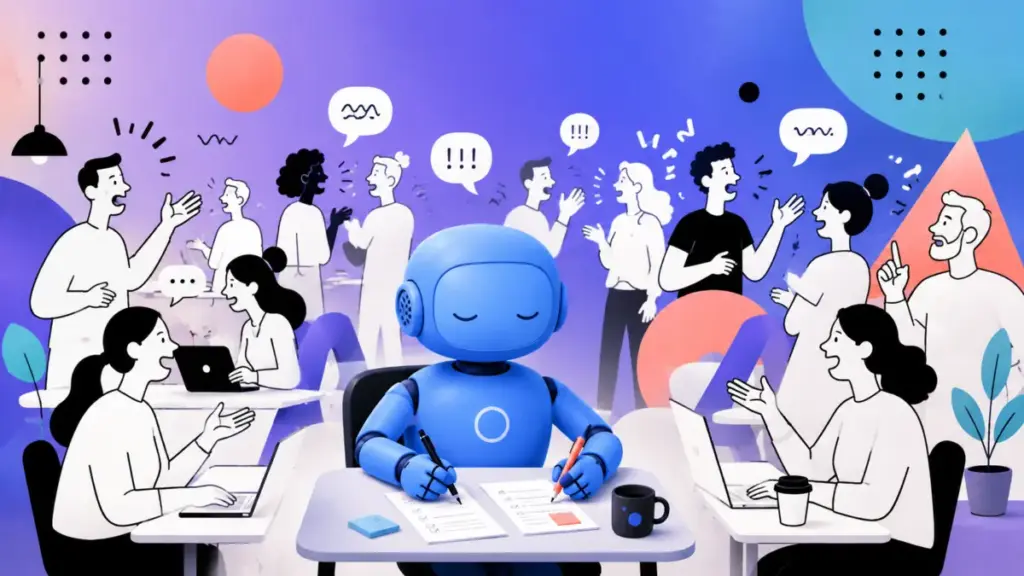
Meta is officially entering the high-stakes, increasingly competitive real-time speech-to-text market with the launch of Muse Voice Transcribe, a sophisticated audio perception model that aims to redefine the balance between performance and cost. Developed by Meta’s Superintelligence Labs, the new offering integrates streaming transcription, precise endpoint detection, and robust speaker diarization for more than 20 participants—all at a highly aggressive public API price point of just $0.18 per hour of processed audio.
As the demand for ambient AI, live meeting assistants, and sophisticated call analytics surges across the enterprise sector, Meta’s entry is positioned to disrupt a market currently occupied by specialized players and major cloud providers. Unlike traditional transcription systems that require a recording to be completed before processing begins, Muse is engineered for the immediate demands of real-time interaction. It processes speech as it occurs, facilitating a seamless flow of information that is critical for applications where latency is the primary enemy of user experience.
The launch post from Meta highlights the model’s versatility, noting its capability to handle long-form audio sessions exceeding one hour, as well as complex features like seamless multilingual code-switching, language and keyword biasing, and high-fidelity diarization. Notably, this diarization is performed natively, meaning developers do not need to implement a separate, complex post-processing pipeline to identify who is speaking. The model was trained across a massive dataset spanning more than 70 languages, with 25 of those languages having been extensively validated for this initial release to ensure high-quality output.
The Evolution of Diarization in the Voice Stack
To understand the significance of Muse, one must first recognize the fundamental shift occurring in the voice technology stack. Traditional automatic speech recognition (ASR) has historically focused on a singular, binary question: "What was said?" However, modern enterprise AI requirements have evolved. For a transcript to be useful in a corporate setting, it must answer a second, equally critical question: "Who said it?"
This distinction is far from academic. For meeting assistants, customer service analytics, and compliance workflows, the accuracy of speaker attribution is the difference between a reliable corporate record and a liability. If a system incorrectly attributes a legal commitment, a financial approval, or a contentious objection to the wrong participant, the entire downstream utility of the AI is compromised. By incorporating speaker attribution directly into its autoregressive, multimodal architecture, Muse aims to solve this at the foundational level.
Meta’s approach to this architecture is highly technical. Audio enters the system in 80-millisecond chunks—roughly 12.5 chunks per second—with each segment transformed into a soft token. At every step of the process, the model performs a dynamic calculation, deciding whether to consume additional audio input or to commit to emitting text. Meta refers to this as "adaptive delay." Rather than relying on a rigid latency budget that applies uniformly to every word, the system is designed to exercise patience when the incoming speech is ambiguous and to act with speed when it has gathered sufficient context. This behavior is refined through reinforcement learning, which optimizes for a balance between word-error-rate (WER) and the delay reward.
The integration of speaker attribution and endpointing into this same token sequence is a significant design choice. The model utilizes specialized tokens, such as a <|start_of_turn|> marker, to signal potential changes in speakers, alongside identifiers like <|speaker_A|> to label the participant. By training the ASR, diarization, and endpointing functions concurrently, rather than treating speaker clustering as a secondary, unrelated process, Meta has built a more cohesive model that understands the relationship between the sound, the identity, and the timing of human speech.
Evaluating Speaker Capacity and Market Positioning
While Meta’s support for 20-plus speakers is an impressive technical achievement, it is important to contextualize this figure within the broader industry landscape. A review of existing vendor documentation reveals that while 20 participants represent a high-end capability for most real-time systems, it is not the highest published ceiling in the industry.
For instance, Speechmatics’ real-time transcription service explicitly states that it can identify 50 speakers by default, with the capacity to scale up to 100 speakers for specific use cases. Similarly, Amazon Transcribe’s documentation specifies a maximum of 30 unique speakers for its streaming transcription services. Other providers, such as Soniox and AssemblyAI, report lower caps, often citing the inherent difficulty of performing accurate live attribution when the system lacks the "future" audio context available in offline, asynchronous models.
It is also worth noting that Meta has not yet demonstrated the 20-plus speaker limit in a live production environment in its marketing materials. Its primary live demonstrations showcase eight speakers, while its long-form recording examples feature 11 participants. Consequently, the 20-plus figure should be viewed as a stated model capability rather than a demonstrated floor for every concurrent session. However, for most enterprise applications—where meetings typically involve far fewer than 20 people—the specific ceiling is often less relevant than the overall reliability of the system.
A Competitive Price-Performance Proposition
Perhaps the most disruptive aspect of Muse is its pricing model. At $0.18 per hour, Meta is positioning itself at the aggressive end of the market, particularly when compared to competitors that levy additional fees for diarization features.
When standardizing the costs across the industry, the competitive landscape becomes clear. Soniox, at approximately $0.12 per hour, currently holds a lower base rate for its real-time service. However, many other providers sit significantly higher on the cost spectrum. For example, Deepgram’s Nova-3 Multilingual streaming rate is roughly $0.35 per hour, but once the $0.12 per hour diarization add-on is applied, the cost rises to $0.47. Similarly, AssemblyAI’s Universal-3.5 Pro Realtime service starts at $0.45, with an additional $0.12 charge for streaming diarization, bringing the total to $0.57 per hour.
Meta’s pricing is straightforward: $3 per 1,000 minutes, with no hidden surcharges for the diarization components that are bundled into the base model. Furthermore, Meta maintains pricing parity between streaming and non-streaming transcription, and it does not charge extra for zero-data-retention processing. This makes the math simple for enterprise developers: at 1,000 hours of audio, the cost is roughly $180.
While the comparison is complex due to varying regional pricing, volume tiers, and subscription models—such as Cartesia’s credit-based system or the blended token costs of Google’s Gemini—Meta’s strategy is unmistakable. It is leveraging its scale to offer a high-performance, feature-rich model that undercuts most of the established market, effectively forcing competitors to justify their higher prices through differentiation rather than just basic functionality.
Accuracy as a Strategic Differentiator
Meta’s value proposition is bolstered by its performance in independent benchmarks. According to the Artificial Analysis AA-WER (Word Error Rate) Streaming Index, Muse has secured a top-tier position with a 3.1% error rate. This performance outpaces several industry mainstays, including Cartesia Ink-2 (3.4%), ElevenLabs Scribe v2 (3.6%), and various iterations of models from Google, OpenAI, and AssemblyAI, which often fall in the 3.9% to 4.0% range.
Even more impressive is Meta’s reported diarization error rate. In testing across standard datasets like AMI-IHM, AMI-SDM, and VoxConverse, Meta reports an average error rate of 17.5%, which it claims is lower than competing systems.
Despite these strong numbers, developers must account for certain deployment trade-offs. The current Muse API provides turn-level timestamps rather than word-level ones and does not offer built-in emotion detection or sound-event detection, which some specialized competitors do provide. Additionally, the default configuration supports eight concurrent streams per tenant and requires a reconnection after 60 minutes of continuous session time.
Ultimately, Meta’s entry into this space suggests that the era of basic, "transcription-only" models is coming to a close. By bundling high-capacity, low-latency diarization into a single, affordable, and highly accurate package, Meta is shifting the industry conversation away from raw speech-to-text conversion and toward the intelligence and identity layers of voice technology. For developers building the next generation of AI agents and meeting intelligence tools, the question is no longer just how much a transcription costs, but how well that system can parse the complexities of human interaction in real-time.