Meta has officially entered the increasingly crowded real-time speech-to-text market with the introduction of Muse Voice Transcribe. Developed by the company’s Superintelligence Labs, the new audio perception model aims to disrupt the landscape by offering a sophisticated, all-in-one solution that combines streaming transcription, precise endpoint detection, and robust speaker diarization for more than 20 participants. By pricing its public API at just $0.18 per hour of processed audio, Meta is positioning itself as a formidable competitor to established industry players.
Unlike legacy systems that require an audio file to be fully recorded before processing begins, Muse is engineered for the immediacy of real-time interaction. It is designed to process speech as it happens, a critical requirement for modern applications like live meeting assistants, customer service analytics, and ambient AI systems. Meta’s launch documentation highlights that the model supports long-form audio exceeding an hour, allows for seamless multilingual code-switching, and features language and keyword biasing. Furthermore, it achieves speaker diarization—the process of identifying "who spoke when"—without the need for a separate, resource-heavy post-processing pipeline. The model arrives with support for over 70 languages, with 25 of them having undergone extensive validation for the initial release.
Diarization as a Core Component of the Modern Voice Stack
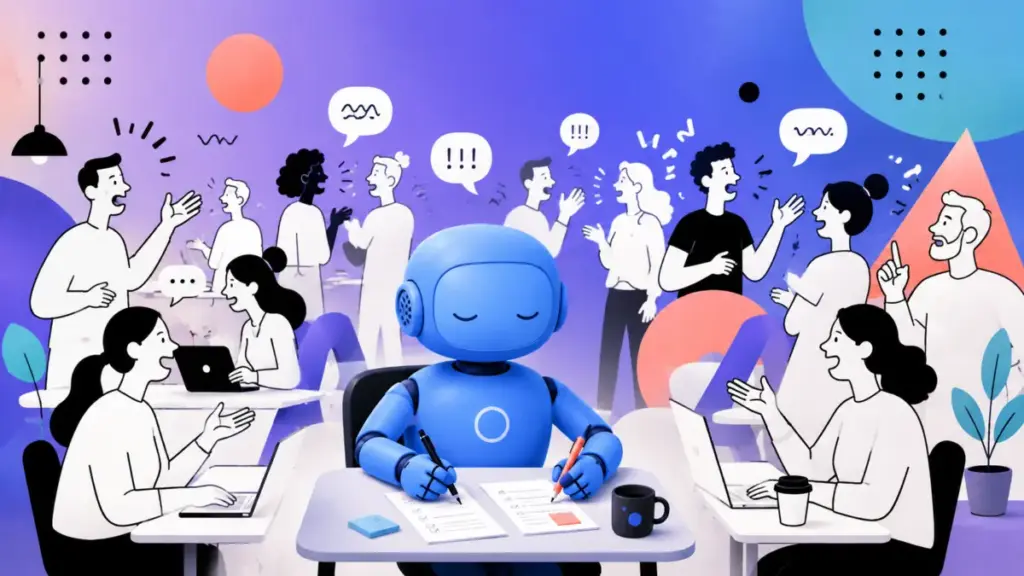
In the evolution of speech technology, the focus has shifted from simple transcription to contextual understanding. Traditional automated speech recognition (ASR) systems were tasked with answering a single question: "What was said?" However, as these transcripts increasingly serve as the foundation for downstream AI agents and large language models, the question of "Who said it?" has become equally important.
This distinction is more than a technical nuance; it is a fundamental requirement for business reliability. If a meeting assistant accurately captures every word of a corporate discussion but misattributes a critical commitment, approval, or objection to the wrong participant, the resulting record becomes fundamentally flawed. This challenge is particularly acute in complex environments such as customer-service analytics, legal compliance workflows, and collaborative AI agents operating in rooms with multiple speakers.
To address this, Muse integrates speaker attribution directly into its autoregressive multimodal architecture. Meta’s technical approach involves breaking down incoming audio into 80-millisecond chunks, processing roughly 12.5 chunks per second. Each chunk is transformed into a "soft token." At every step, the model dynamically decides whether to consume additional audio for context or to emit text immediately. This "adaptive delay" mechanism allows the system to remain flexible; it can wait longer when speech is ambiguous and commit to a transcription when it has sufficient confidence. By utilizing reinforcement learning, Meta has trained the model to balance word-error-rate and latency, ensuring that the system is both accurate and responsive.
Within this architecture, speaker attribution and endpointing are woven into the same token sequence as the transcription itself. Specialized tokens—such as <|start_of_turn|> to mark a new speaker and <|speaker_A|> to label them—allow the model to distinguish between participants in real time. Because the ASR, diarization, and endpointing are trained together, the system avoids the errors often associated with running speaker clustering as an unrelated downstream process.
Evaluating Speaker Capacity Claims
Meta’s claim that Muse can support more than 20 speakers is substantial, though it does not represent a global record. A review of current vendor documentation reveals that several industry incumbents offer higher published ceilings. For instance, Speechmatics’ real-time transcription service explicitly states that it can identify 50 speakers by default, a capacity that can be increased to 100 upon request. Similarly, Amazon Transcribe’s documentation specifies a maximum of 30 unique speakers for its streaming transcription services.
Other providers are more conservative. Soniox, which provides both real-time and asynchronous processing, documents a limit of 15 speakers per session. AssemblyAI, another major player, allows developers to configure a max_speakers parameter between one and 10 for its streaming diarization system. Both companies have noted in the past that live speaker attribution is significantly more complex than offline processing, as the system must make high-stakes decisions with limited access to "future" audio context. Meanwhile, xAI’s current Speech-to-Text API also supports streaming diarization, though its documentation does not explicitly publish a maximum speaker count, making a direct comparison with Muse difficult.
It is also worth noting that Meta’s own promotional material does not demonstrate the 20-speaker capacity in a live environment. Its principal demonstration showcases eight speakers, and its long-form sample contains 11 labeled participants. The 20-plus figure is, therefore, a stated architectural capability rather than a demonstrated limit in public use cases. Nonetheless, for the vast majority of enterprise use cases—such as board meetings, small-group interviews, or customer calls—a 20-speaker ceiling is more than sufficient, suggesting that Meta is prioritizing real-world utility over the pursuit of high-volume, niche records.
An Aggressive Push on Pricing
Perhaps the most significant aspect of Meta’s entry into this market is its pricing strategy. At $0.18 per hour of audio, Meta is positioning itself at the low end of the market. Its pricing model is straightforward: $3 per 1,000 minutes, with billing rounded down to the nearest second. Critically, Meta does not charge a premium for streaming versus non-streaming, nor does it impose extra fees for zero-data-retention processing.
This pricing is highly competitive when compared to other industry offerings. While Soniox, at $0.12 per hour, remains one of the most affordable options, many other providers charge significantly more, especially when diarization is factored in as an add-on. For example, while Deepgram’s base rate for its Nova-3 model is roughly $0.35 per hour, adding diarization increases the cost to approximately $0.47 per hour. Similarly, AssemblyAI’s base rate for its Universal-3.5 Pro Realtime model is $0.45, with an additional $0.12 per hour for streaming diarization.
By including diarization as a first-class, built-in feature of the model at a flat $0.18 per hour, Meta is effectively forcing a re-evaluation of the total cost of ownership for voice-enabled applications. For enterprises processing thousands of hours of audio, this could result in significant cost savings, putting pressure on competitors to justify their price structures, especially those that charge for speaker attribution as a separate, metered component.
Performance and Market Positioning
Meta’s competitive stance is bolstered by its own accuracy benchmarks. According to the Artificial Analysis Streaming Index, which tracks performance across the industry, Muse recorded a 3.1% word error rate (WER) as of early September. This placed it ahead of several notable competitors, including Cartesia’s Ink-2 at 3.4%, ElevenLabs’ Scribe v2 at 3.6%, and various models from Google, OpenAI, and AssemblyAI, which hovered between 3.9% and 4.0%.
The diarization performance is equally compelling. Meta reports an average diarization error rate of 17.5% across benchmarks like AMI-IHM and VoxConverse, claiming this outperforms the competing systems shown in its internal testing. While these results are promising, it is important to note that speaker capacity and diarization accuracy are distinct metrics. A model that can technically support 100 speakers is not necessarily better at correctly attributing speech than one capped at 20.
As with any new technology, there are trade-offs to consider. Muse’s API currently provides turn-level timestamps rather than word-level ones, and it lacks certain advanced features found in other platforms, such as emotion detection, sound-event detection, or word-level confidence scores. Additionally, the default configuration supports eight concurrent streams per tenant and limits sessions to 60 minutes, after which a reconnection is required.
Despite these limitations, the arrival of Muse Voice Transcribe signals a shift in the enterprise AI landscape. By bundling high-capacity diarization, low-latency transcription, and aggressive pricing into a single model, Meta is providing developers with a powerful new tool. For companies building the next generation of meeting intelligence, live transcription services, and voice-activated AI, the focus will increasingly shift toward the "all-in-one" efficiency that Muse represents. As the market matures, the ability to maintain accurate speaker attribution during complex, unfolding conversations will likely become the primary metric by which these platforms are measured, rather than raw speech-to-text accuracy alone.