BREAKING NEWS
Open Source Modernizing Drupal Development: Integrating Cypress for Robust End-to-End Testing 6 hours ago Data Science & Big Data OpenRouter Simplifies Multi-Model AI Development in Python with a Unified API 6 hours ago IoT & Smart Home Amazon’s $500 Echo Show 16 Wants to Be the Center of Your Home 6 hours ago Space Tech Flexell Space and Satoro Partner for In-Orbit Demonstration of Next-Generation Space Solar Cells on SpaceX Falcon 9 6 hours ago Design & UI/UX Welcoming September in Style: A Global Community Curates New Desktop Wallpaper Collection 6 hours ago Tech Education & Careers Building a Passwordless Future: Implementing Secure Passkey Authentication with WebAuthn, Next.js, and NestJS 6 hours ago Artificial Intelligence Meta Enters Real-Time Transcription Market with Competitive Muse Voice Transcribe Model 14 hours ago Cybersecurity Suspected ShinyHunters Leader Detained in Jordan, Reportedly Cooperating with FBI 14 hours ago Software Development GitHub Unveils High-Efficiency Secret Scanning Pipeline to Combat Credential Leaks 14 hours ago Cloud Computing Beyond the Horizon: AWS Reflects on the Staggering Scale of Prime Day 2026 14 hours ago Open Source Modernizing Drupal Development: Integrating Cypress for Robust End-to-End Testing 6 hours ago Data Science & Big Data OpenRouter Simplifies Multi-Model AI Development in Python with a Unified API 6 hours ago IoT & Smart Home Amazon’s $500 Echo Show 16 Wants to Be the Center of Your Home 6 hours ago Space Tech Flexell Space and Satoro Partner for In-Orbit Demonstration of Next-Generation Space Solar Cells on SpaceX Falcon 9 6 hours ago Design & UI/UX Welcoming September in Style: A Global Community Curates New Desktop Wallpaper Collection 6 hours ago Tech Education & Careers Building a Passwordless Future: Implementing Secure Passkey Authentication with WebAuthn, Next.js, and NestJS 6 hours ago Artificial Intelligence Meta Enters Real-Time Transcription Market with Competitive Muse Voice Transcribe Model 14 hours ago Cybersecurity Suspected ShinyHunters Leader Detained in Jordan, Reportedly Cooperating with FBI 14 hours ago Software Development GitHub Unveils High-Efficiency Secret Scanning Pipeline to Combat Credential Leaks 14 hours ago Cloud Computing Beyond the Horizon: AWS Reflects on the Staggering Scale of Prime Day 2026 14 hours ago
Stories
Modernizing Drupal Development: Integrating Cypress for Robust End-to-End Testing
OpenRouter Simplifies Multi-Model AI Development in Python with a Unified API
Amazon’s $500 Echo Show 16 Wants to Be the Center of Your Home
Flexell Space and Satoro Partner for In-Orbit Demonstration of Next-Generation Space Solar Cells on SpaceX Falcon 9
Welcoming September in Style: A Global Community Curates New Desktop Wallpaper Collection
Building a Passwordless Future: Implementing Secure Passkey Authentication with WebAuthn, Next.js, and NestJS
Meta Enters Real-Time Transcription Market with Competitive Muse Voice Transcribe Model
Suspected ShinyHunters Leader Detained in Jordan, Reportedly Cooperating with FBI
GitHub Unveils High-Efficiency Secret Scanning Pipeline to Combat Credential Leaks
Beyond the Horizon: AWS Reflects on the Staggering Scale of Prime Day 2026
Apple Launches iOS 27.2: Major CarPlay Enhancements and Siri AI Integration
Jio Platforms Makes Historic Stock Market Debut, Surging 21% Following India’s Largest IPO

Tag: inference

3 posts

Standard

The Hidden Infrastructure Crisis: Why AI Inference Latency Is Breaking Production Kubernetes

It is Thursday afternoon, roughly fifteen minutes past two, and your organization’s internal AI assistant has been live for precisely two weeks. Initially launched as a quiet pilot, the demo went well enough that a finance executive inquired if the tool could read through complex corporate contracts. Word quickly spread across departments. Today, for the…
Read more
Standard

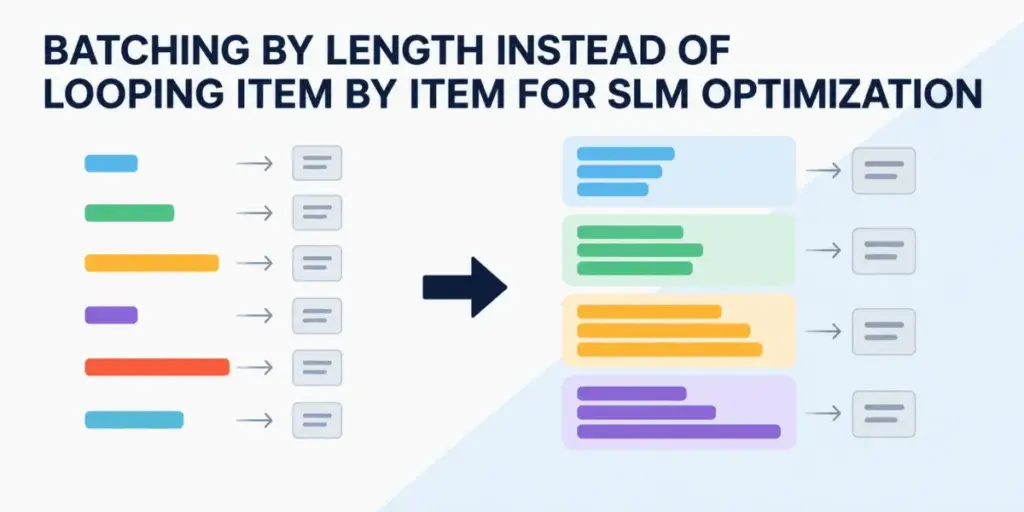
Optimizing Small Language Models: Boosting Inference Throughput with Length-Bucketed Batching

As artificial intelligence deployment shifts increasingly toward edge devices and local hardware, engineering teams are finding that raw model capability is only half the battle. Efficient execution matters just as much, particularly when deploying small language models (SLMs) for narrow, high-frequency automation tasks. In the final installment of a technical series examining performance optimization for…

Read more
Standard

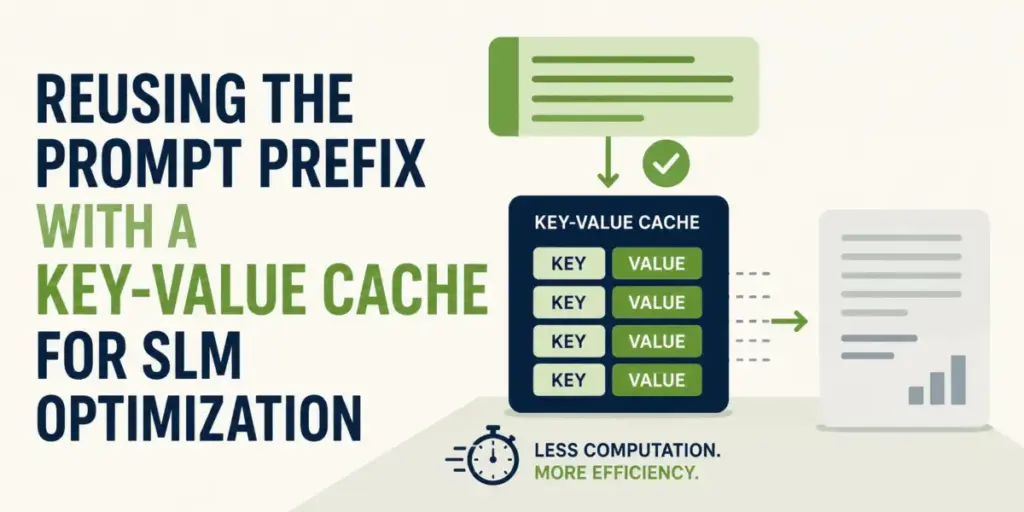
Boosting Small Language Model Efficiency: How Key-Value Prefix Caching Cuts Inference Costs by Over 50 Percent

As organizations increasingly look toward edge deployments and localized workloads, small language models (SLMs) have emerged as powerful engines for narrow automation tasks. However, achieving production-grade efficiency requires moving beyond standard inference loops that treat every API call or model execution as an isolated event. In the second installment of a technical series focused on…

Read more

You May Have Missed

Catch up on interesting stories you might have overlooked