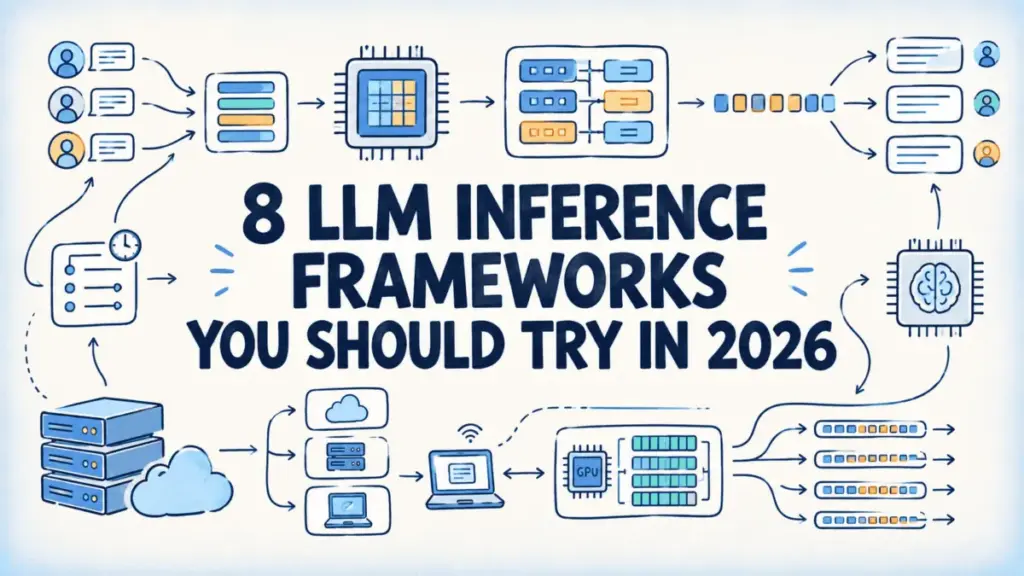
As large language models (LLMs) transition from experimental Jupyter notebooks into high-demand enterprise environments, the underlying infrastructure required to run them has grown increasingly sophisticated. A model operating in a standard development notebook typically handles a single request at a time, easily fitting into available memory. In stark contrast, a modern production endpoint must process numerous concurrent requests simultaneously. Each incoming prompt demands precise allocation of GPU memory for its key-value (KV-cache), an active slot in the batch processing queue, and a continuous, low-latency response stream.
While foundational libraries like PyTorch or Hugging Face Transformers provide the necessary raw building blocks to load and execute models, they leave the complex orchestration layers—such as dynamic request scheduling, efficient memory cache management, and robust API serving—entirely up to the engineering team. Building this underlying machinery from scratch for every deployed model is inefficient and technically daunting. To bridge this gap, specialized inference frameworks have emerged as critical middleware. Positioned directly between the raw machine learning model and user-facing applications, these engines optimize token generation, manage KV-cache memory allocation, handle intelligent request batching, and supply standardized API surfaces. Implementing a suitable inference framework allows the exact same hardware to serve significantly higher volumes of concurrent requests with reduced latency, all without altering the underlying model weights.
The current landscape of inference optimization spans two distinct operational poles. On one side are high-throughput, data-center-scale serving engines designed to maximize resource utilization across massive GPU clusters. On the other are lightweight, highly portable tools engineered for local workstations, edge devices, and resource-constrained environments. Understanding the strengths and operational profiles of these frameworks is vital for developers designing modern AI architectures.
Leading the charge in high-throughput data center environments is vLLM, widely recognized as one of the most heavily adopted engines for scalable LLM deployment. Engineering teams migrating away from standard PyTorch or Transformers pipelines frequently choose vLLM as their first step into optimized serving. Its architecture is engineered to solve memory fragmentation issues inherent in traditional serving methods, allowing data centers to maximize their hardware investments through advanced batching and memory management techniques. For organizations scaling models across multiple processing units, vLLM offers robust support for tensor parallelism, enabling seamless distribution of massive models across GPU clusters.
Closely following in the enterprise space is SGLang, a framework that distinguishes itself by pairing a high-performance backend runtime with a dedicated frontend language tailored for describing complex model interactions. This dual approach makes SGLang particularly well-suited for advanced workloads that rely on intricate prompting logic, multi-step reasoning, and structured generation tasks. By optimizing the execution graph alongside the serving runtime, SGLang reduces the computational overhead typically associated with complex programmatic LLM pipelines.
For organizations demanding absolute control over hardware execution, Modular’s MAX serving framework offers kernel-level optimization. Designed to bridge the gap between high-level AI models and low-level hardware performance, MAX provides developers with granular tuning capabilities. This deep level of control allows engineering teams to extract maximum computational efficiency out of their specific hardware configurations, whether deploying on specialized accelerators or standard enterprise infrastructure.
In environments heavily standardized around NVIDIA hardware, TensorRT-LLM serves as the premier inference library. Because the library is meticulously engineered by NVIDIA to exploit the architectural nuances of its own proprietary GPUs, organizations operating homogeneous NVIDIA fleets routinely experience substantial performance gains and speed optimizations. The setup investment required to configure TensorRT-LLM is typically offset by the raw throughput and latency reductions achieved in production environments.
Another prominent contender in the data-center tier is LMDeploy, a comprehensive toolkit focused heavily on model compression, deployment speed, and serving efficiency. By prioritizing advanced quantization techniques and high-performance decoding throughput, LMDeploy enables organizations to run larger models on fewer resources while maintaining strict latency service-level agreements. Its specialized execution engine targets NVIDIA hardware to deliver rapid response times under heavy concurrent loads.
Shifting the focus from data centers to local and edge environments, llama.cpp has established itself as an indispensable tool for lightweight, portable inference. Written entirely in plain C and C++ with virtually no external dependencies, this runtime supports a vast array of prominent model families, including Llama, Qwen, DeepSeek, and Mistral. Its minimalist design footprint allows developers to execute sophisticated models efficiently on consumer-grade hardware and local central processing units without requiring massive cloud infrastructure.
Complementing this local developer experience is Ollama, which abstracts the complexities of model downloading, versioning, and local serving behind an intuitive command-line interface and straightforward API. By packaging these processes into a unified tool, Ollama has become a ubiquitous starting point for developers experimenting with LLMs locally on laptops and workstations before pushing applications to production environments.
Rounding out the ecosystem is MLC-LLM, a compiler-based engine built upon the Apache TVM framework. This tool addresses unique deployment challenges where target hardware is non-standard or applications must span multiple platforms seamlessly. By compiling model weights specifically for the target execution environment, MLC-LLM enables efficient deployment across diverse hardware architectures, ranging from desktop GPUs to mobile phones and web browsers.
Ultimately, selecting the appropriate inference framework requires a careful evaluation of specific traffic patterns, available hardware infrastructure, and ultimate deployment targets. As the AI industry continues to mature in 2026, rigorous benchmarking of latency and cost against operational models remains the most reliable path to successful system architecture.