BREAKING NEWS
Artificial Intelligence The Shift to Answer Engine Optimization: Why Marketing Teams Must Rethink Brand Visibility 6 hours ago Cybersecurity Massive Dark Web Breach Exposes 153 Million North American Driver’s Licenses; FBI Launches Investigation 6 hours ago Software Development How GitHub Security Lab is Using AI Agents to Uncover Complex Android Vulnerabilities 6 hours ago Cloud Computing Amazon S3 Tables Expands Capabilities with Full Support for Apache Iceberg V3 Specification 6 hours ago Gadgets & Hardware The Router Dilemma: Evaluating the Benefits of Buying Versus Renting Your ISP Hardware 6 hours ago Startups & Venture Capital Pinterest Unveils ‘Beauty Guides’ to Bridge the Gap Between Digital Inspiration and Salon Reality 6 hours ago Cryptocurrency & Blockchain Arbitrum Joins Paxos-Led Global Dollar Network to Capture Digital Dollar Revenue 6 hours ago Mobile Technology Leaked Preview Highlights Enhanced PDF Workflow on Upcoming iPhone Duo 6 hours ago Gaming & VR Star Wars: Galactic Racer Joins Amazon Luna Lineup as 2026 Gaming Success Story 6 hours ago Open Source From Token to Contributor: Navigating Diversity Initiatives, Imposter Syndrome, and Open Source Growth 6 hours ago Artificial Intelligence The Shift to Answer Engine Optimization: Why Marketing Teams Must Rethink Brand Visibility 6 hours ago Cybersecurity Massive Dark Web Breach Exposes 153 Million North American Driver’s Licenses; FBI Launches Investigation 6 hours ago Software Development How GitHub Security Lab is Using AI Agents to Uncover Complex Android Vulnerabilities 6 hours ago Cloud Computing Amazon S3 Tables Expands Capabilities with Full Support for Apache Iceberg V3 Specification 6 hours ago Gadgets & Hardware The Router Dilemma: Evaluating the Benefits of Buying Versus Renting Your ISP Hardware 6 hours ago Startups & Venture Capital Pinterest Unveils ‘Beauty Guides’ to Bridge the Gap Between Digital Inspiration and Salon Reality 6 hours ago Cryptocurrency & Blockchain Arbitrum Joins Paxos-Led Global Dollar Network to Capture Digital Dollar Revenue 6 hours ago Mobile Technology Leaked Preview Highlights Enhanced PDF Workflow on Upcoming iPhone Duo 6 hours ago Gaming & VR Star Wars: Galactic Racer Joins Amazon Luna Lineup as 2026 Gaming Success Story 6 hours ago Open Source From Token to Contributor: Navigating Diversity Initiatives, Imposter Syndrome, and Open Source Growth 6 hours ago
Stories
The Shift to Answer Engine Optimization: Why Marketing Teams Must Rethink Brand Visibility
Massive Dark Web Breach Exposes 153 Million North American Driver’s Licenses; FBI Launches Investigation
How GitHub Security Lab is Using AI Agents to Uncover Complex Android Vulnerabilities
Amazon S3 Tables Expands Capabilities with Full Support for Apache Iceberg V3 Specification
The Router Dilemma: Evaluating the Benefits of Buying Versus Renting Your ISP Hardware
Pinterest Unveils ‘Beauty Guides’ to Bridge the Gap Between Digital Inspiration and Salon Reality
Arbitrum Joins Paxos-Led Global Dollar Network to Capture Digital Dollar Revenue
Leaked Preview Highlights Enhanced PDF Workflow on Upcoming iPhone Duo
Star Wars: Galactic Racer Joins Amazon Luna Lineup as 2026 Gaming Success Story
From Token to Contributor: Navigating Diversity Initiatives, Imposter Syndrome, and Open Source Growth
The High-Stakes Clash Over AI Data Centers: Who Pays When the Grid and Water Systems Strain?
Voice Assistant Weather Face-Off: Which AI Platform Gets the Forecast Right?

Tag: language

9 posts

Standard

Mastering Large Language Model Efficiency: Five Proven Techniques for Token Compression and Prompt Optimization

In the rapidly evolving landscape of artificial intelligence development, large language models have become the cornerstone of modern software architecture. Whether deployed in enterprise production applications or evaluated inside experimental notebooks, developers face a persistent economic and technical challenge: every token counts. Bloated and inefficient prompts silently drain operational budgets while simultaneously degrading response quality.…

Read more
Standard

KDnuggets Releases New Cheat Sheet to Help Developers Master Local Language Model Management with Ollama

Running artificial intelligence language models directly on local hardware has evolved to a point of remarkable simplicity. For developers, data scientists, and hobbyists alike, the fundamental hurdle of getting a model up and running has largely shifted away from complex setup procedures toward more nuanced operational challenges. Tools like Ollama have streamlined the initial deployment…

Read more
Standard

The Reality of Real-Time Translation: How Modern Earbuds Are Breaking Down Language Barriers

For decades, the concept of a "universal translator"—a device capable of instantly bridging the gap between disparate languages—was relegated to the realm of science fiction. Today, that vision is inching toward reality. We are witnessing a technological evolution where the dream of fluent, cross-cultural conversation without the need for human interpreters is becoming increasingly accessible.…

Read more
Standard

GitHub Copilot Introduces Canvas Extensions: Redefining the Developer Interface Through Natural Language

For decades, software development has been defined by the rigid boundaries of the tools we use. Developers have long been forced to adapt their workflows to the fixed screen layouts, limited menu options, and static data representations provided by their IDEs and project management software. If a tool provided a kanban board, you used a…

Read more
Standard

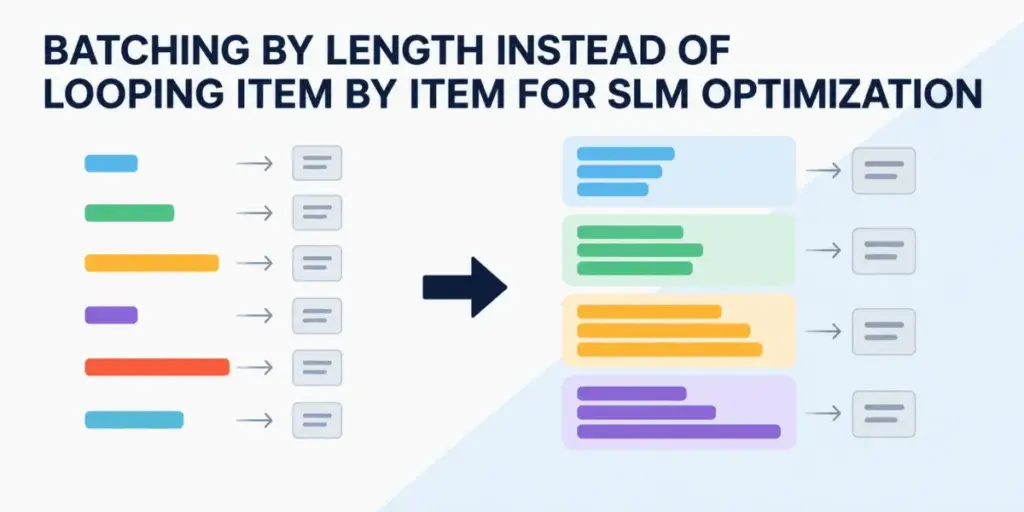
Optimizing Small Language Models: Boosting Inference Throughput with Length-Bucketed Batching

As artificial intelligence deployment shifts increasingly toward edge devices and local hardware, engineering teams are finding that raw model capability is only half the battle. Efficient execution matters just as much, particularly when deploying small language models (SLMs) for narrow, high-frequency automation tasks. In the final installment of a technical series examining performance optimization for…

Read more
Standard

The Shift to Local AI: Exploring Seven Open-Source Frontends for Self-Hosted Language Models

The artificial intelligence landscape is undergoing a subtle yet profound shift. A growing number of users, developers, and organizations are moving away from purely cloud-based setups, choosing instead to run advanced machine learning models directly on their own hardware. Driven by a demand for heightened privacy, stricter data control, and predictable operating costs, this movement…

Read more
Standard

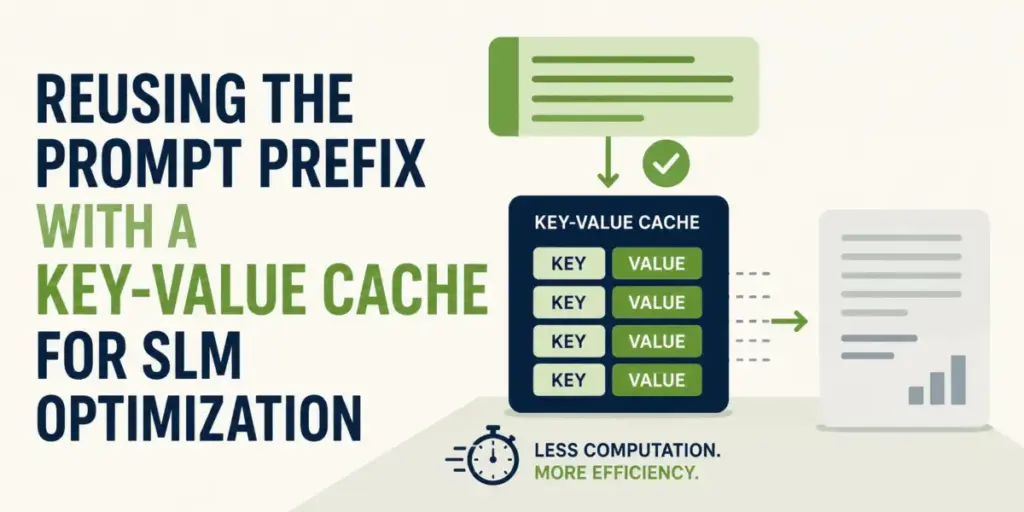
Boosting Small Language Model Efficiency: How Key-Value Prefix Caching Cuts Inference Costs by Over 50 Percent

As organizations increasingly look toward edge deployments and localized workloads, small language models (SLMs) have emerged as powerful engines for narrow automation tasks. However, achieving production-grade efficiency requires moving beyond standard inference loops that treat every API call or model execution as an isolated event. In the second installment of a technical series focused on…

Read more

You May Have Missed

Catch up on interesting stories you might have overlooked