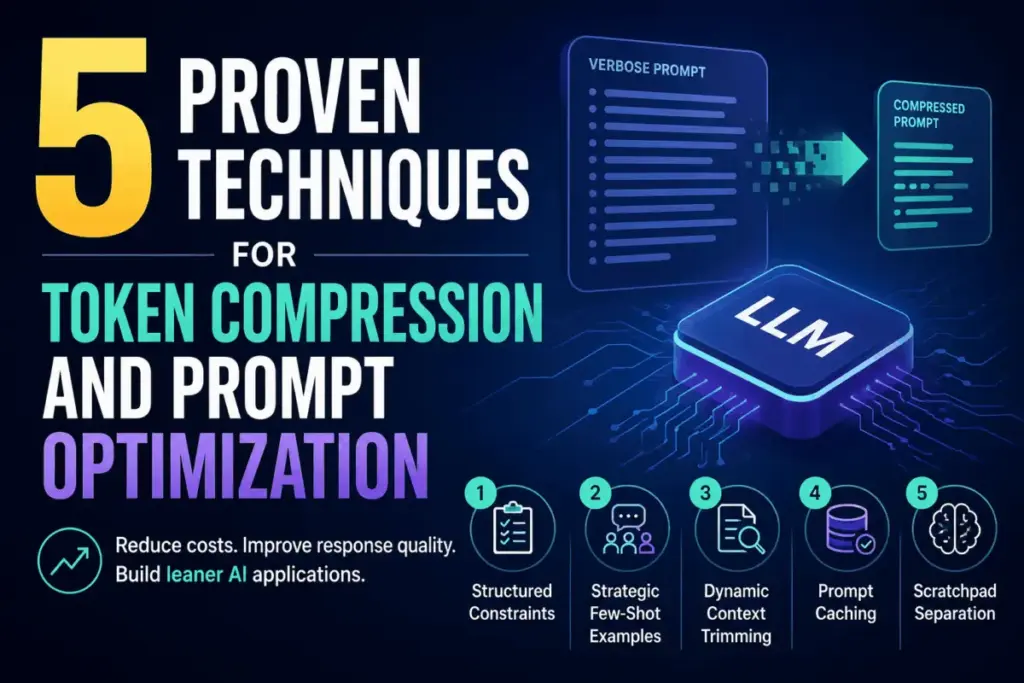
In the rapidly evolving landscape of artificial intelligence development, large language models have become the cornerstone of modern software architecture. Whether deployed in enterprise production applications or evaluated inside experimental notebooks, developers face a persistent economic and technical challenge: every token counts. Bloated and inefficient prompts silently drain operational budgets while simultaneously degrading response quality. Addressing this industry-wide hurdle, AI and data science educator Vinod Chugani has outlined five proven techniques for token compression and prompt optimization, offering developers a roadmap to transmit more intent with fewer tokens.
Token compression is fundamentally the practice of maximizing semantic value per token, while prompt optimization governs how that intent is structured so that models can respond with high accuracy and efficiency. Without these optimizations, applications handling thousands of daily API calls quickly run into unsustainable costs and sluggish response times. To counter this, practitioners are increasingly moving away from conversational, narrative-heavy prompts toward precise, highly structured architectural patterns that reduce consumption without sacrificing output quality.
Replacing Verbose Instructions with Structured Constraints
The first major source of inefficiency stems from the natural inclination to write system prompts using polite, conversational language. While these long instructions feel intuitive to human writers, they carry a heavy financial and computational penalty when processed by large language models. The industry solution involves transitioning from narrative descriptions to declarative constraints, employing schema-like formatting that underlying models can parse with maximum efficiency.
For example, traditional prompts often rely on extensive descriptive paragraphs to dictate formatting rules, negative constraints, and length limitations. By compressing these instructions into pipe-delimited key-value pairs, YAML-style constraints, or model-specific JSON schema snippets, developers can drastically reduce token counts. A single concise line of structured constraints can replace dozens of conversational tokens. As these patterns scale across thousands of production API calls, the resulting cumulative savings compound rapidly, proving that brevity and structural discipline are essential for sustainable AI deployment.
Using Few-Shot Examples Strategically, Not Exhaustively
Few-shot prompting, which involves providing a series of input-output examples before the actual user request, remains one of the most effective ways to ensure consistent output formatting. However, a common pitfall among practitioners is the tendency to provide an exhaustive list of examples under the assumption that more data invariably yields better results.
Recent research from major AI laboratories and academic benchmarks consistently demonstrates clear diminishing returns beyond three to five examples for standard classification and generation tasks. Establishing a lean pattern with just three robust examples is typically sufficient to prime the model effectively. Adding excessive examples rarely improves accuracy and frequently introduces subtle contradictions that confuse the model during inference. Industry experts recommend auditing existing few-shot repositories and benchmarking performance at varying example thresholds to find the optimal balance before committing to bloated prompt designs.
Applying Dynamic Context Trimming for Long Documents
Passing extensive source materials—such as legal transcripts, knowledge base articles, or lengthy technical documentation—directly into a prompt often forces developers to pay for vast amounts of contextual data that the model does not actually need to complete the task. Dynamic context trimming solves this problem by retrieving only the specific relevant passages required for a given query rather than flooding the model with the entire raw document.
By implementing lightweight similarity algorithms, such as cosine similarity calculations using sentence embeddings, applications can filter and rank document sections before constructing the final prompt. When applied to massive knowledge repositories where only a tiny fraction of the overall text is contextually relevant, dynamic trimming can slash context token costs by dramatic margins. This targeted approach not only reduces operational expenses but also helps mitigate the attention degradation that models sometimes suffer when forced to process excessively long input sequences.
Caching Repeated Prompt Prefixes with Prompt Caching
Many enterprise applications repeatedly send identical system prompts across every individual user request, duplicating static persona definitions, tool descriptions, and policy constraints on every turn. Transmitting these unchanging tokens fresh with every single API call represents a significant, unnecessary overhead. To address this, several major inference providers now support server-side prompt caching and automatic prefix caching.
Under these caching frameworks, static prompt prefixes are stored and reused directly on the server side, with providers billing cached tokens at a fraction of standard input pricing. To maximize this capability, developers must structure their prompts hierarchically, placing stable, static content at the very beginning and shifting dynamic user messages to the end. By understanding and leveraging provider-specific caching thresholds and time windows, engineering teams can drastically lower their recurring infrastructure costs.
Compressing Chain-of-Thought Reasoning with Scratchpad Separation
Chain-of-thought prompting is widely recognized for its ability to significantly enhance model reasoning capabilities when tackling complex logic or multi-step problems. However, the internal reasoning trace generated by the model—often spanning hundreds of tokens—frequently appears verbatim in the final API response, even when the application requires nothing more than the final answer. This phenomenon inflates output token consumption and drives up costs unnecessarily.
To resolve this issue, developers are increasingly adopting scratchpad separation techniques, using structured output markers to isolate the reasoning steps from the final deliverable. By instructing the model to perform its step-by-step calculations inside designated tags, applications can parse and discard the verbose thinking block while storing and returning only the concise answer to the end user. For APIs that natively support extended thinking or dedicated reasoning modes, these internal tokens may be billed differently and suppressed from the standard response body entirely.
Ultimately, these optimization strategies highlight a broader shift toward engineering precision within the artificial intelligence ecosystem. By adopting structured constraints, strategic few-shot sizing, dynamic context trimming, prefix caching, and scratchpad separation, organizations can systematically eliminate token waste. As large language model usage continues to scale across global industries, even modest per-call savings translate into substantial financial reductions and faster, more responsive applications.