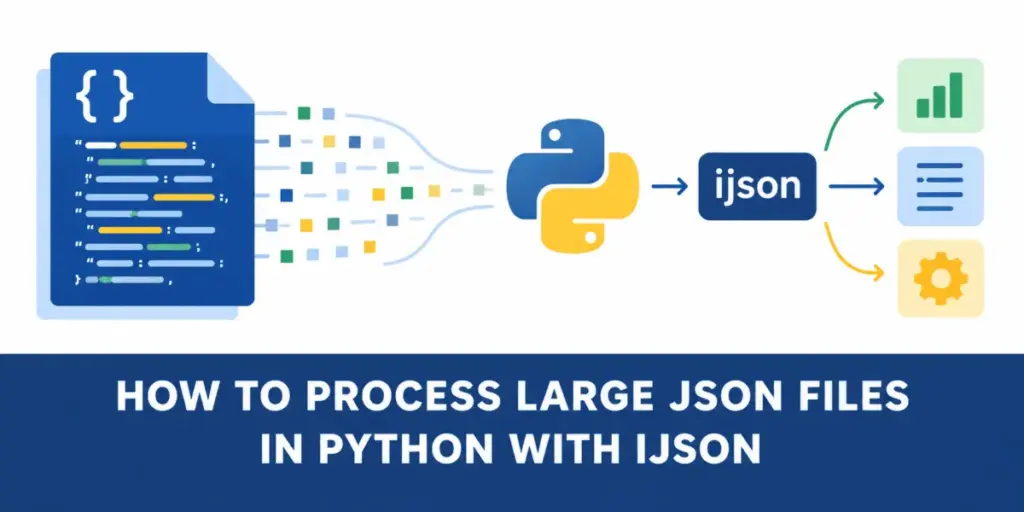
In the modern landscape of data engineering and software development, JavaScript Object Notation, widely known as JSON, has established itself as one of the most ubiquitous formats for storing and exchanging information. Its human-readable syntax and native compatibility with numerous programming environments make it a staple for web applications, APIs, and data storage systems. For developers working within the Python ecosystem, handling smaller JSON files has long been a trivial task, largely thanks to the built-in json module. With a simple method call, developers can ingest entire files into memory and immediately begin analyzing or manipulating the underlying data structures.
However, this conventional approach exposes a significant vulnerability when projects scale up to handle massive datasets. A growing number of software engineers and data scientists are discovering that traditional parsing methods crumble under the weight of files measuring several hundred megabytes or gigabytes. When engineers attempt to process large-scale JSON documents using standard loading functions, their applications frequently encounter severe memory bottlenecks, leading to sluggish performance, system crashes, or unexpected out-of-memory terminations. The root of the issue lies not within the JSON format itself, but rather in the way traditional parsers handle the translation from disk storage to active memory.
To understand the mechanics of this widespread memory issue, experts point to the fundamental behavior of standard parsing utilities. When a developer executes a traditional loading command on a JSON document, the parser is forced to read the entire file into active memory at once. During this phase, it parses every single object, array, string, number, and boolean value, translating them into corresponding Python data structures such as dictionaries, lists, and floats. Consequently, a file that occupies a relatively modest amount of disk space can expand exponentially once it is fully instantiated in random-access memory.
This dramatic inflation occurs because every individual element, key-value pair, and nested array requires its own overhead allocation within the Python runtime environment. For instance, a dataset containing complex geographical coordinates, nested property attributes, and extensive arrays will consume memory far exceeding the raw file size on disk. In environments with constrained resources, such as standard cloud instances or local development machines, this sudden spike in memory consumption can completely paralyze an application before any meaningful data analysis even begins.
To demonstrate this phenomenon and explore viable alternatives, technical researchers frequently turn to real-world datasets that mirror the scale of modern production environments. A prime example is the San Francisco City Lots dataset, a comprehensive collection of land-parcel records distributed in the standard GeoJSON FeatureCollection format. Weighing in at approximately 181 megabytes, this dataset is sufficiently large to highlight the stark differences between traditional loading techniques and more modern streaming approaches, yet manageable enough to analyze within experimental environments like Google Colab.
An examination of the dataset’s internal structure reveals a root object containing metadata followed by an expansive array of features. Each feature represents an individual land parcel, divided primarily into two distinct sections: property attributes and geometric coordinates. The properties section contains granular details such as block numbers, lot numbers, and street names, while the geometry section houses intricate polygon coordinates detailing the precise boundaries of each parcel on a map.
In many practical scenarios, an analyst might only require a fraction of this information—such as isolating parcels located on a specific thoroughfare. Yet, when employing a standard parsing approach, the Python runtime has no awareness of these selective filtering intentions beforehand. It must painstakingly load every single polygon, vertex, and coordinate point into memory, regardless of whether the analysis ultimately requires that data.
When developers implement the conventional loading method on such a dataset, the execution flow forces the interpreter to read the complete file, parse every object, construct thousands of dictionaries and lists, and store the entire collection in active memory before the first line of analytical code can execute. Profiling tools designed to monitor resource utilization during this process vividly illustrate the heavy toll this approach takes on system architecture. Memory consumption spikes dramatically the moment the file is parsed, remaining at peak levels throughout the execution of the script.
This stark reality has driven developers to seek alternative methodologies that decouple file size from memory consumption. Rather than forcing an entire document into active memory all at once, engineers are increasingly adopting iterative parsing strategies. Iterative parsers allow applications to stream data incrementally, processing individual records as they flow through the pipeline and discarding them immediately afterward.
In the Python ecosystem, libraries designed for iterative parsing have emerged as powerful tools for managing large-scale data workflows. By leveraging these streaming parsers, developers can target specific paths within a massive JSON document, extracting individual items from large arrays without ever constructing the entire document tree in memory. This paradigm shift fundamentally alters the resource requirements of data-intensive applications.
When applied to the San Francisco land-parcel dataset, an iterative parsing approach demonstrates a dramatic reduction in peak memory consumption. Instead of requiring hundreds of megabytes of RAM to hold the entire collection of parcels, the streaming approach maintains a remarkably stable and minimal memory footprint throughout the execution cycle. The parser reads a single feature, hands it over to the processing logic, evaluates the necessary conditions, and then releases the memory associated with that record before moving on to the next.
While this streaming methodology requires a slight shift in how developers structure their data pipelines, the performance benefits in resource-constrained environments are profound. Industry experts emphasize that iterative parsers do not necessarily guarantee faster execution times in every scenario; if a system possesses an abundance of free RAM, traditional loading functions may still complete certain tasks rapidly. Instead, the primary advantage of streaming JSON data lies in its predictability and stability. By ensuring that memory consumption remains flat regardless of whether a file is one hundred megabytes or ten gigabytes in size, developers can build robust applications capable of scaling seamlessly alongside growing data volumes.