 Standard
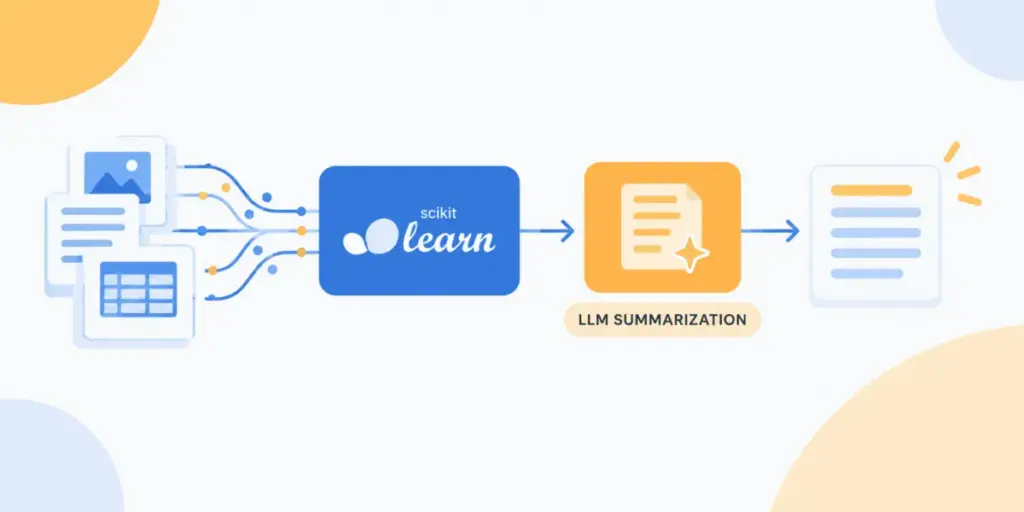
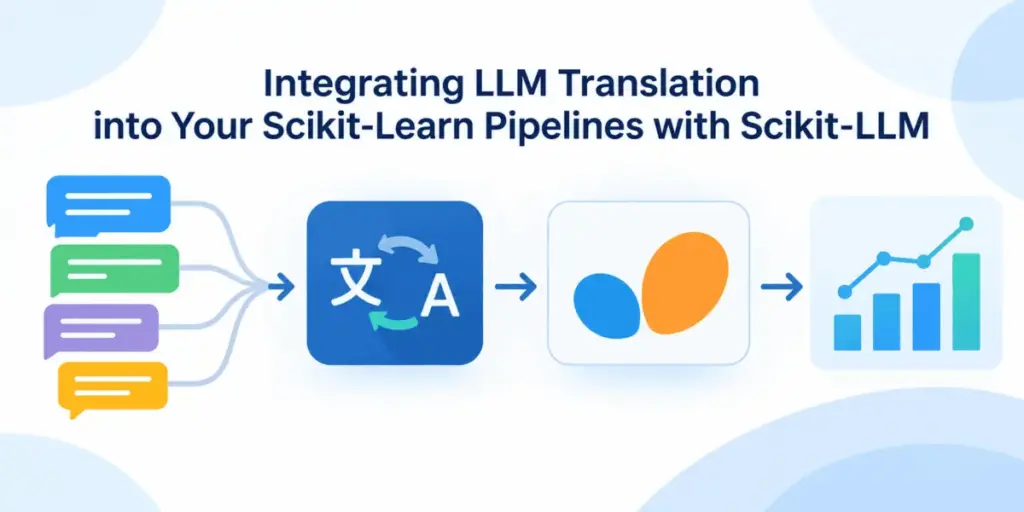
Integrating LLM Translation and Zero-Shot Classification Into Scikit-Learn Pipelines
Text classification has long remained a cornerstone of natural language processing, yet real-world applications frequently introduce a persistent logistical hurdle: processing raw text data written across multiple, disparate languages. Before any downstream machine learning model can accurately categorize or interpret incoming inputs, data scientists must typically normalize the multilingual text into a single, unified language.…