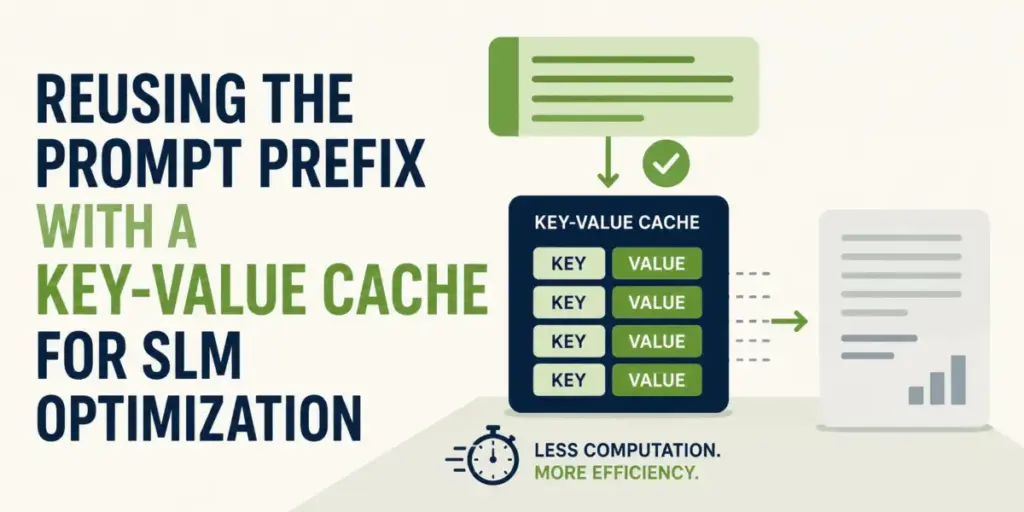
As organizations increasingly look toward edge deployments and localized workloads, small language models (SLMs) have emerged as powerful engines for narrow automation tasks. However, achieving production-grade efficiency requires moving beyond standard inference loops that treat every API call or model execution as an isolated event. In the second installment of a technical series focused on optimizing SLMs for high-volume, constrained environments, developers and engineers are turning their attention to a critical optimization strategy: reusing the prompt prefix with a key-value cache.
Building upon previous methodologies that constrained the output space of models to streamline decision-making, the latest technical benchmarks demonstrate that caching static prompt components can slash overall compute times by more than half. Utilizing a standard 0.5-parameter instruction-tuned model running on consumer-grade hardware, developers have shown that eliminating redundant token re-encoding transforms SLMs from a resource-heavy compromise into a highly practical, low-latency production choice.
The Redundancy Problem in Narrow Automation
Narrow automation tasks—such as classifying customer support tickets, routing incoming queries, or parsing standardized form fields—rely heavily on structured, repetitive prompts. In a typical production pipeline, a prompt consists of a static instruction block, a detailed taxonomy definition, and several few-shot examples. This foundational content frequently runs to a couple of hundred tokens.
Appended to this static block is a brief, dynamic tail that changes with every individual item—such as a specific customer support ticket adding twenty or thirty tokens. In a standard inference loop, the entire prompt is fed into the transformer model from scratch on every single call. Because the overwhelming majority of every prompt is byte-for-byte identical to the last one, the system repeatedly recomputes key and value vectors for the exact same instruction tokens across every layer of the network.
Transformer architectures compute key and value vectors for each token at every individual layer, and these mathematical representations depend exclusively on the tokens preceding them. Consequently, for a fixed, unchanging prefix, these internal representations are identical on every single execution call. Computing them once, storing them securely in memory, and holding onto them effectively shrinks the per-item pre-fill phase down to only the novel tokens that actually changed from one task to the next.
Benchmarking the Performance Gains
To measure the real-world impact of this optimization, recent benchmarks deployed the Hugging Face Transformers library alongside the Qwen2.5-0.5B-Instruct model operating in float16 precision. The tests were executed on an M2 MacBook Air equipped with 24GB of RAM and a 16-core Neural Engine, utilizing a standardized dataset of 600 customer support tickets divided evenly across three distinct categories: billing, technical, and account inquiries.
In the baseline scenario, where the full prompt containing the 145-token static prefix and the dynamic ticket text was re-encoded for every single record, the model required a total processing time of 184.85 seconds. This translated to an average of approximately 308 milliseconds per ticket. While manageable for low-volume tasks, this approach scales poorly when deployed in high-throughput enterprise environments where latency and CPU resource consumption are critical cost drivers.
By contrast, implementing a prefix caching mechanism altered the performance profile entirely. In this optimized workflow, the static instruction block is processed by the model exactly once at initialization. The resulting key-value tensors are preserved using a dynamic cache structure, allowing subsequent inference calls to feed the model exclusively the new, incoming tokens of each individual support ticket.
When tested across the identical set of 600 records, the cached prompt prefix approach completed the entire classification workload in 80.07 seconds. This reduced the average processing time down to approximately 133.5 milliseconds per ticket, representing an overall runtime reduction of roughly 57 percent. Crucially, because prefix caching is a pure compute optimization rather than an alteration to the model’s underlying weights or inference logic, the classification accuracy and final predictions remain identical to the unoptimized baseline loop.
Implications for Production AI Deployments
The performance gains achieved through key-value prefix caching highlight a fundamental shift in how developers should approach small language model integration. The efficiency dividend of this technique scales directly with the ratio between static and dynamic content within a prompt. Rather than penalizing developers for writing comprehensive, highly detailed instruction blocks and robust few-shot examples, prefix caching actually rewards richer and more explicit system prompts.
As organizations continue to explore edge computing, on-device intelligence, and cost-effective automation pipelines, the viability of sub-billion parameter models depends heavily on architectural efficiency. By eliminating redundant computational overhead through strategies like prefix caching, engineering teams can ensure that small language models operate with the speed and reliability required for modern enterprise workflows.
The findings offer a clear roadmap for practitioners seeking to optimize local inference workloads without sacrificing model behavior or output quality, cementing the role of SLMs as foundational tools for scalable, narrow automation.