A mid-sized engineering team recently received a commercial vendor quote that stunned leadership: fifty thousand dollars to build a custom artificial intelligence model trained specifically on their historical customer support tickets. Highly skeptical of the exorbitant pricing, a lone developer on the team decided to spend a weekend testing the underlying methodology independently. By leveraging modern parameter-efficient tuning techniques on rented cloud infrastructure, the developer successfully trained the model for less than ten dollars in raw graphics processing unit costs.
That massive discrepancy is neither a rounding error nor an isolated incident within the fast-moving artificial intelligence industry. Historically, fine-tuning large language models has carried a reputation as an exclusive research-lab activity. For full-scale training of frontier foundational models from scratch, that reputation remains entirely accurate, with training runs routinely demanding tens or millions of dollars in compute resources. However, adapting existing open-weight models to specialized enterprise tasks has shifted into an entirely different financial category. Most technical guides addressing this economic shift either stop abruptly after explaining a single method or fail to provide transparent, executable code for practitioners.
What Fine-Tuning a Large Language Model Actually Means
Fine-tuning fundamentally alters an existing artificial intelligence model that has already undergone massive pretraining on a broad, general corpus of text. By introducing a narrower, task-specific dataset, the model’s behavior shifts measurably toward exact operational needs—such as adopting a specialized domain vocabulary, adhering to a strict formatting structure, or maintaining a consistent corporate tone—without requiring developers to build a system from the ground up.
When evaluating how to shape model behavior, fine-tuning represents a deliberate architectural commitment rather than the default operational choice. Alternative approaches like prompt engineering, few-shot examples, and retrieval-augmented generation alter outputs dynamically without modifying a single underlying weight. These alternative strategies offer rapid prototyping and effortless updates, making them ideal for preliminary exploration. Fine-tuning, conversely, permanently modifies the internal neural weights of the model itself. Because this constitutes a significantly larger commitment than simply editing a prompt, organizations must carefully evaluate whether adapting weights is genuinely necessary for their specific operational requirements.
Why Teams Actually Fine-Tune
Industry analysis indicates that approximately eighty percent of requests initially framed around the necessity of fine-tuning can actually be solved more efficiently through advanced information retrieval systems. Fine-tuning becomes a durable, high-value capability upgrade under specific operational conditions, such as teaching a model complex structural formats that defy prompt engineering, embedding deeply proprietary domain knowledge that lacks external documentation, or enforcing a rigid behavioral tone across millions of automated interactions. When none of these criteria are met, fine-tuning often serves as an unnecessarily expensive band-aid for flawed prompting or poor data retrieval pipelines.
Which Large Language Models Can Actually Be Fine-Tuned
Before committing to a specific technical approach, development teams must assess which open-weight model families provide mature tooling and active community support. Prominent model families including Llama, Qwen, Mistral, Gemma, and Phi natively support parameter-efficient fine-tuning techniques. For organizations preferring to avoid managing underlying training infrastructure entirely, managed fine-tuning application programming interfaces offered by major platform providers and specialized cloud services present a viable alternative, trading slightly higher per-token costs for zero infrastructure maintenance.
A crucial scaling caveat involves model size and architecture. Parameter-efficient methods run comfortably on single graphics cards when applied to dense models ranging roughly from two billion to thirteen billion parameters. Once models scale past seventy billion parameters, or utilize sparse mixture-of-experts architectures, memory requirements necessitate multi-node hardware clusters merely to hold quantized weights during training operations.
The Real Cost of Fine-Tuning a Large Language Model
Financial realities in the artificial intelligence sector reflect a wide spectrum of expenses depending on the chosen methodology. Parameter-efficient adaptations on smaller models routinely require less than ten dollars in raw compute time, whereas full-scale enterprise fine-tuning on premium clusters can easily exceed ten thousand dollars. Verified industry rates demonstrate that running low-rank adaptation routines on mid-sized models typically consumes mere hours on standard cloud hardware.
However, raw compute time frequently constitutes the smallest line item in a comprehensive project budget. The primary expenditures stem from high-quality dataset curation, multiple iterative training runs, and rigorous evaluation protocols—efforts that must be repeated whenever a base model receives an upstream update. Consequently, comprehensive real-world projects frequently total thousands of dollars in labor and iteration expenses even when underlying compute costs remain minimal.
Algorithmic Efficiency Through Low-Rank Adaptation
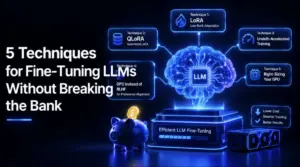
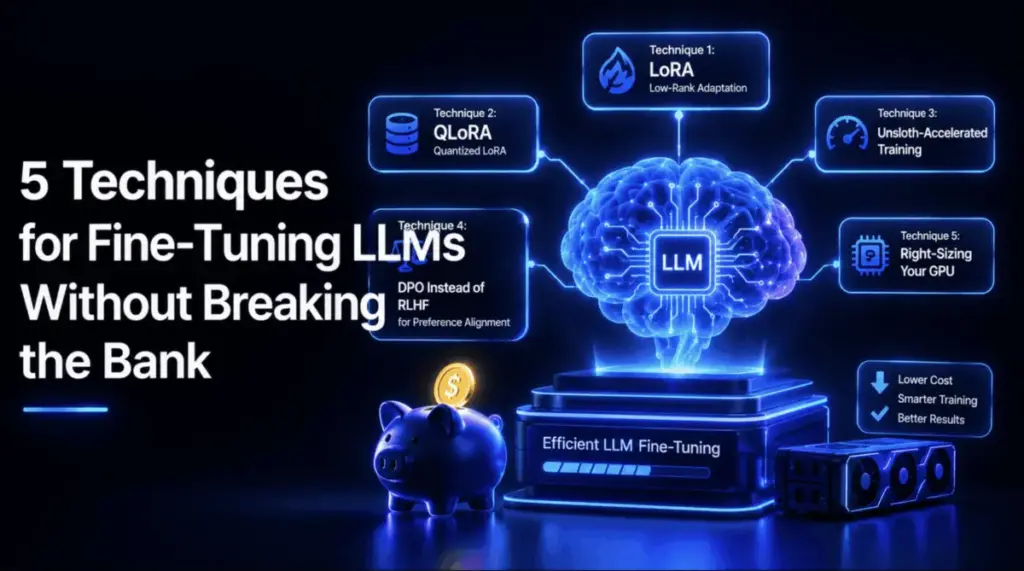
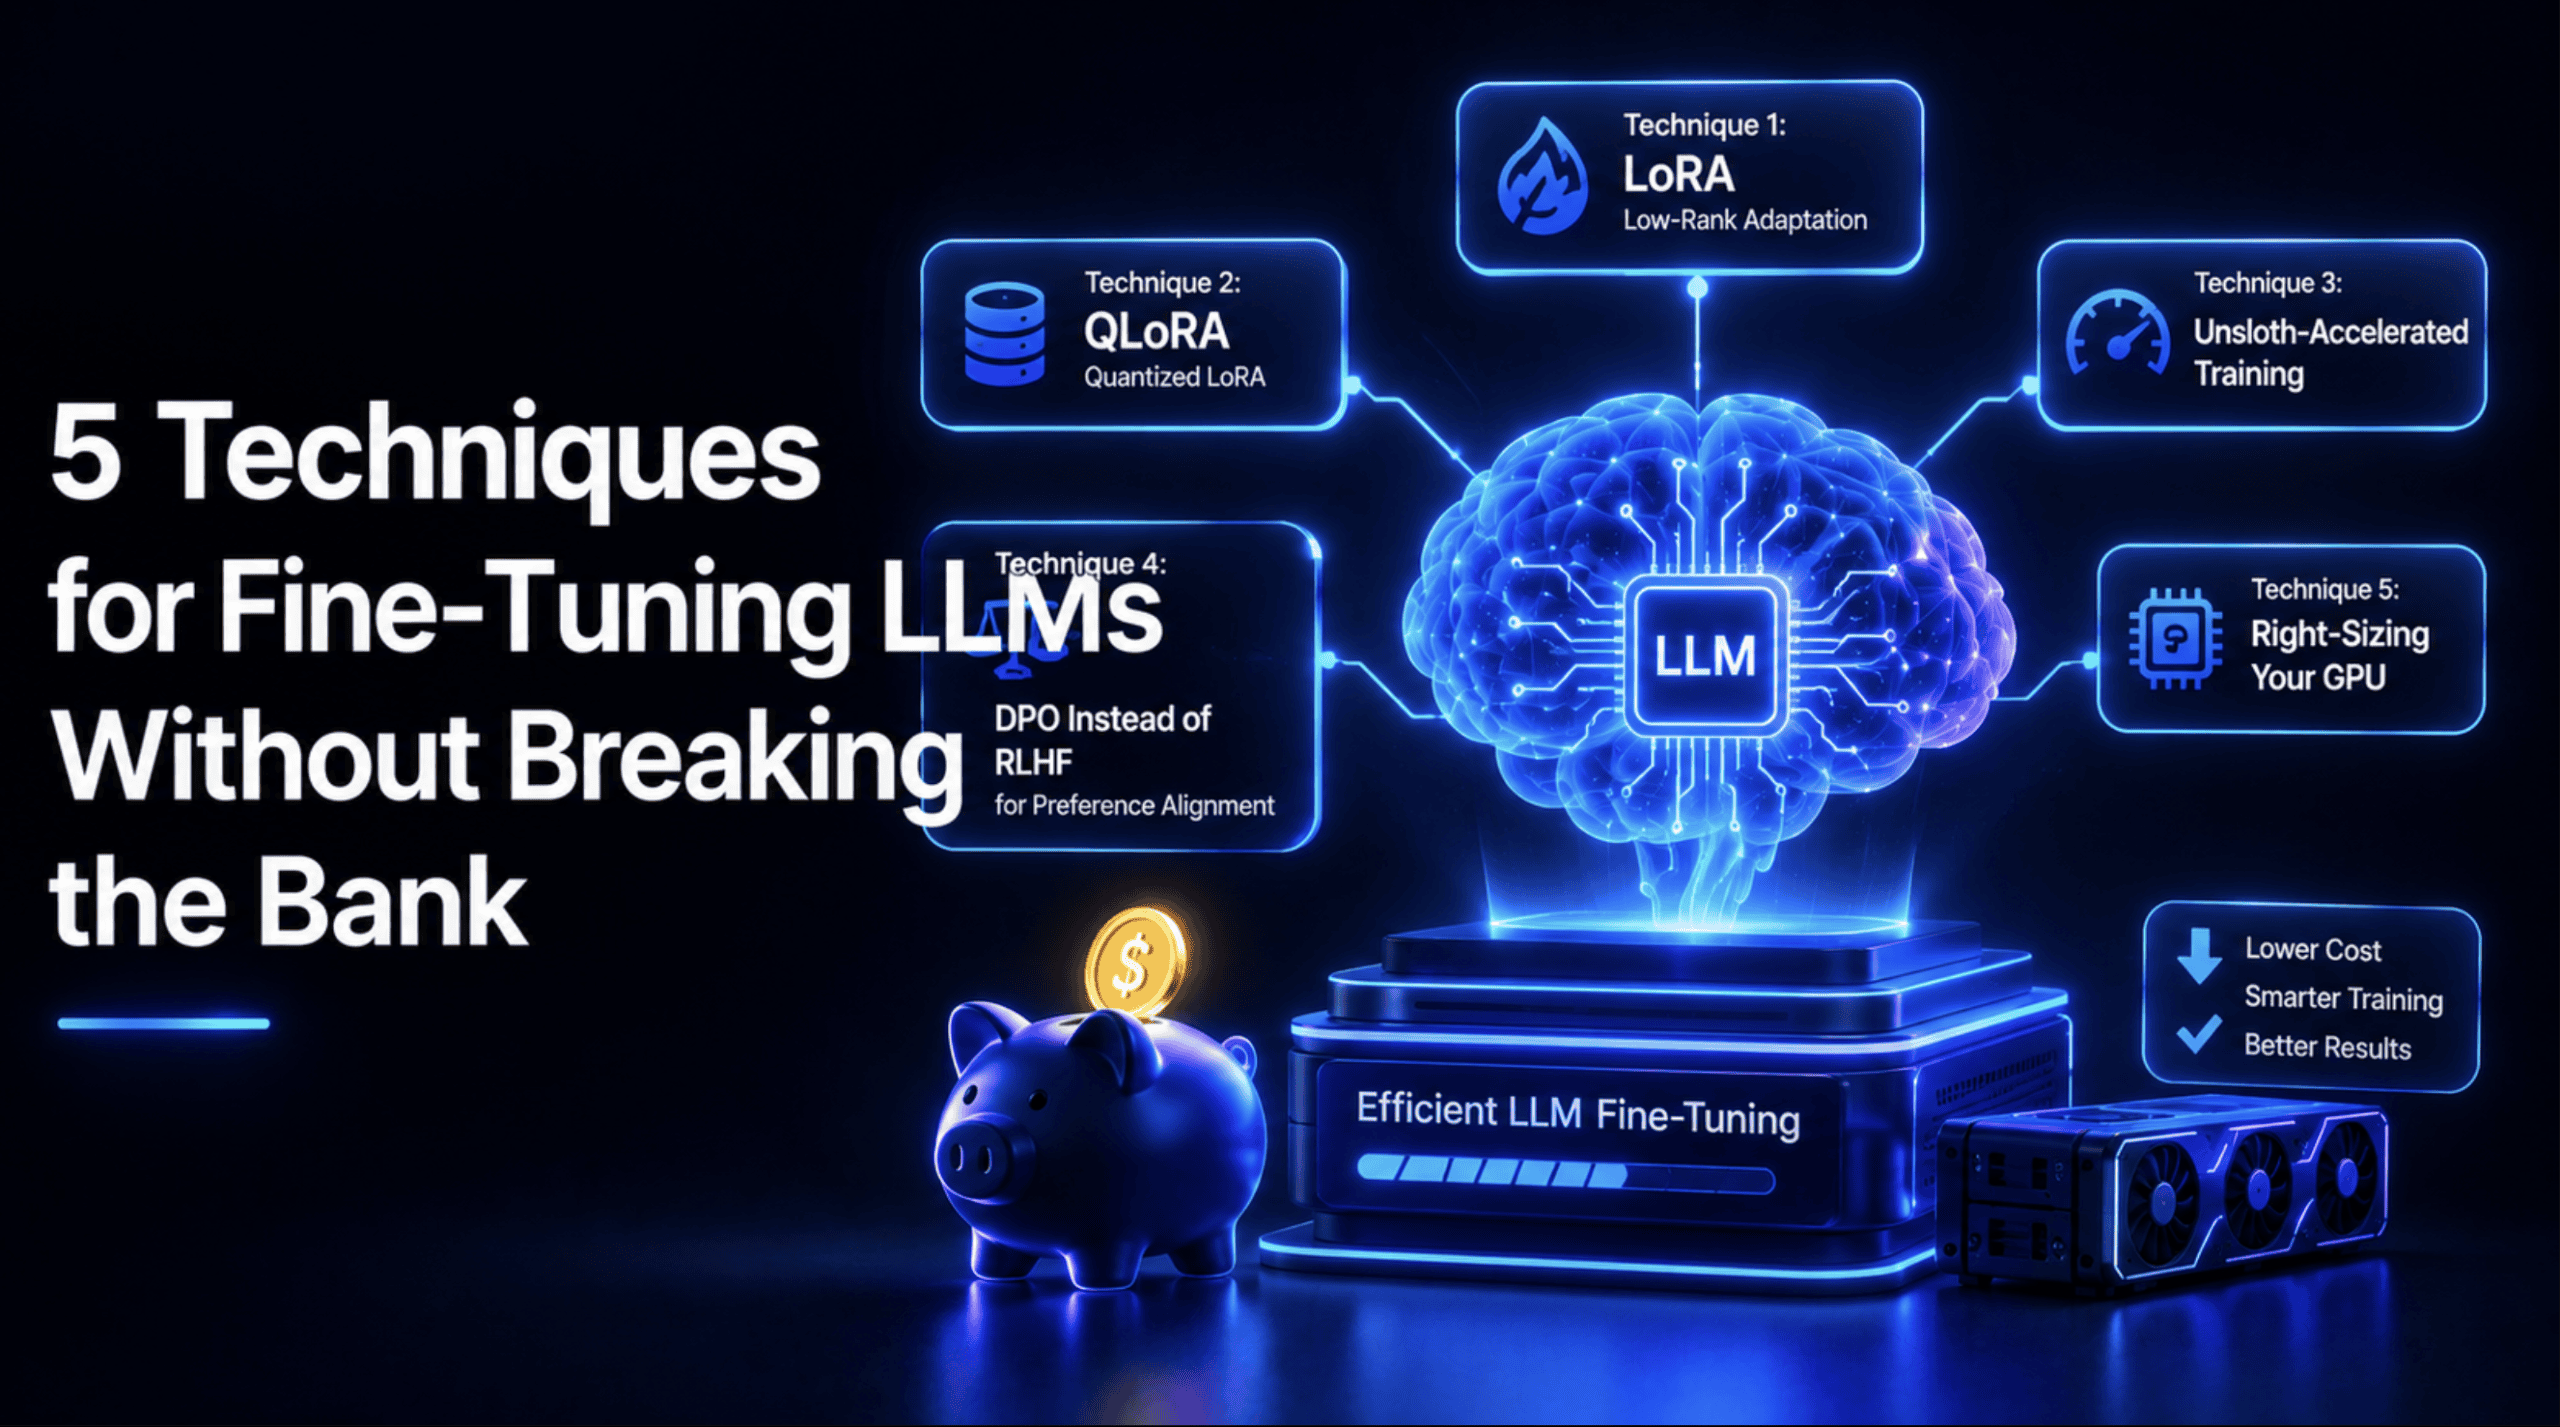
Low-rank adaptation serves as the foundational algorithmic technique that underpins modern cost-effective fine-tuning. Instead of modifying millions or billions of parameters across an entire neural network during training, this methodology freezes the base model completely and injects small, trainable low-rank matrices alongside existing weight layers. Rooted in the mathematical observation that necessary behavioral adaptations possess low intrinsic rank, the approach trains a tiny fraction of total parameters—frequently less than one percent—while leaving original foundational weights entirely untouched.
Overcoming Memory Bottlenecks With Quantization
While foundational low-rank adaptation dramatically reduces the number of trainable parameters, running the underlying base model still demands substantial video random access memory. Quantized low-rank adaptation resolves this hardware limitation by compressing the frozen base model down to four-bit precision while maintaining the trainable adapters in higher precision. This engineering breakthrough successfully reduces overall memory consumption by approximately fourfold, allowing developers to execute complex fine-tuning routines on affordable consumer-grade hardware rather than expensive professional clusters.
Accelerating Workflows With Optimized Tooling
Beyond algorithmic adjustments, specialized training tooling provides further economic relief by replacing standard computing operations with hand-optimized execution kernels. These optimizations directly reduce wall-clock training times and peak memory footprints for identical adaptation setups. Because cloud computing resources bill strictly by the hour, minimizing the total duration of a training run yields immediate, first-order financial savings for development teams.
Streamlining Alignment Without Reinforcement Learning
Supervised fine-tuning teaches models to reproduce example outputs, but aligning a model to prefer specific conversational styles or safety behaviors has traditionally required complex reinforcement learning pipelines. Classical reinforcement learning from human feedback requires training a separate reward model based on human preferences and executing delicate policy optimization algorithms against it. This introduces significant infrastructure overhead and training instability.
Direct preference optimization bypasses the reward model entirely by training directly on ranked pairs of responses using a classification-style loss function. By pushing the model toward preferred responses and away from rejected alternatives without maintaining a secondary model in the loop, development teams can achieve robust preference alignment with a fraction of the computational overhead.
Strategic Hardware Procurement
The single most common and easily avoidable financial mistake in enterprise artificial intelligence projects involves renting ultra-premium hardware tiers for tasks that standard consumer-grade graphics cards can handle with equal efficiency. Prior to provisioning cloud resources, engineering teams must evaluate expected dataset sizes, token volumes, and estimated training throughput to determine the appropriate hardware tier. If preliminary calculations indicate a training duration of less than an hour, renting high-end enterprise nodes represents unnecessary financial waste, whereas larger datasets and iterative workflows justify scaling up to premium infrastructure to save valuable engineering hours.
By strategically stacking algorithmic parameter efficiency, memory quantization, optimized software runtimes, streamlined alignment objectives, and right-sized hardware procurement, organizations can successfully build customized artificial intelligence models at a fraction of historically projected budgets.