Large language models have fundamentally transformed how organizations approach text generation, but they continue to grapple with a well-documented and stubborn limitation: they hallucinate. When operating without direct access to verified, up-to-date information, these models can confidently produce plausible-sounding answers that are factually incorrect. To combat this issue, Retrieval-Augmented Generation, commonly known as RAG, emerged as the industry standard solution. By grounding model outputs in external knowledge sources, RAG dramatically reduced the frequency of hallucinations across a wide variety of enterprise applications.
However, as organizations push these artificial intelligence systems into increasingly complex workflows, a new operational bottleneck has surfaced. Standard RAG pipelines are inherently linear, executing a single retrieval operation, passing those results to the model, and generating a final answer. While this approach functions effectively for simple queries and well-structured knowledge bases, the architecture begins to break down when faced with complex challenges. When a query demands multi-step reasoning, the cross-referencing of multiple distinct sources, or the synthesis of information that is scattered across separate documents, traditional pipelines struggle to deliver accurate results.
This limitation has spurred the development and adoption of Agentic RAG. Rather than treating information retrieval as a single, fixed step in a pipeline, this modern approach equips the system with the capability to reason about how to search, evaluate the quality of what it finds, and iterate continuously until it reaches a genuinely satisfying and reliable answer. Industry experts and data scientists are increasingly evaluating how both architectures function, where standard pipelines reach their breaking points, and what specific capabilities make agentic systems fundamentally better suited for enterprise tasks.
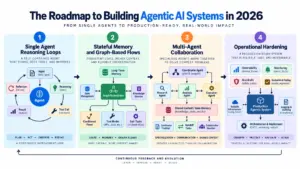
The Baseline: Understanding Naive RAG
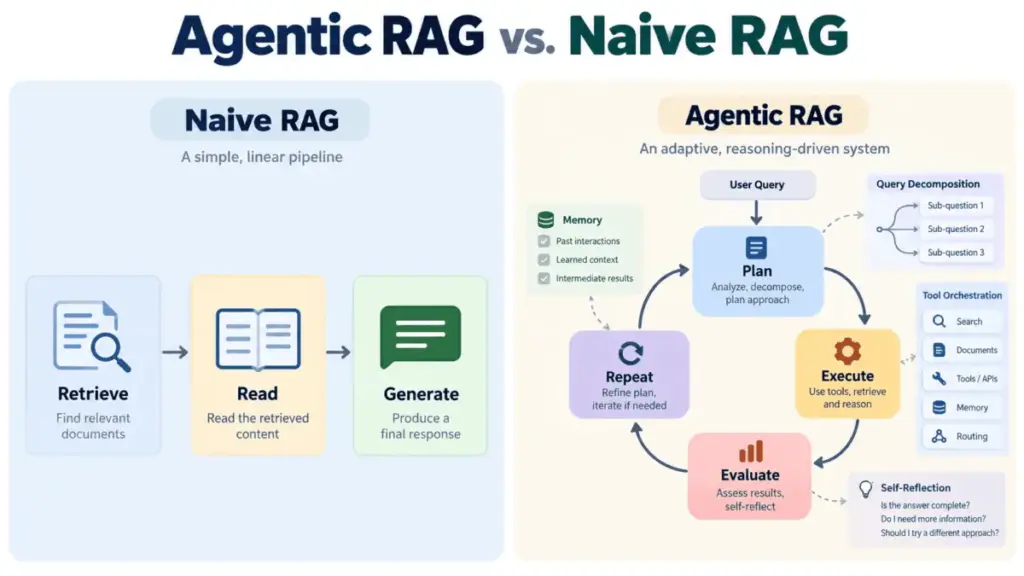
Before examining the evolution of retrieval systems, it is essential to understand the foundation upon which they were built. Naive RAG, frequently referred to as standard RAG, follows a rigid, three-stage pipeline consisting of retrieval, reading, and generation. In this traditional setup, a user submits a query, and the system converts that text into a vector embedding. It then executes a similarity search against a vector database, retrieves a predetermined number of the most relevant document chunks, and passes those chunks to the large language model as context. The model subsequently generates a response based exclusively on the provided text.
To visualize this process, consider a student preparing for an examination in a massive library. Naive RAG operates like a student who types a single keyword into the catalog, grabs the first three books on the shelf, and writes an essay using only the material directly in front of them, without pausing to verify whether those sources actually answer the core question.
Under the hood, the technical mechanics are straightforward. When documents are initially ingested, they are divided into smaller chunks and converted into dense vector representations using an embedding model. These vectors are housed in a database optimized for approximate nearest-neighbor searches. At inference time, the user’s query undergoes the same embedding process, and the database returns the chunks whose vectors reside closest in high-dimensional space. These retrieved segments are then injected directly into the context window of the large language model as reference material.
This architecture represented a genuine breakthrough for enterprise technology. Naive RAG made it feasible to construct reliable enterprise question-and-answer systems, internal knowledge assistants, and document summarization tools that remained anchored to verified sources. For numerous straightforward applications, it remains an efficient and cost-effective choice.
The Bottleneck: Where Naive RAG Breaks Down
Despite its initial success, the core architectural weakness of standard RAG lies in its linearity. A single retrieval pass either succeeds or fails. If an initial query is poorly formulated, if the relevant information is distributed across multiple documents, or if the answer necessitates reasoning across several distinct steps, the pipeline possesses no mechanism for recovery.
The single-pass limitation means the system gets only one opportunity to retrieve the right information. If the query’s vector embedding fails to surface the correct document chunks, the model is left generating a response from incomplete or entirely irrelevant context. It cannot recognize that the retrieval operation failed, nor can it attempt an alternative search strategy.
This structural flaw becomes glaringly apparent during multi-step reasoning tasks. Consider a complex query regarding corporate acquisitions and regulatory compliance in the European Union. Answering such a prompt correctly requires at least two distinct informational hops: identifying the parent company that acquired a specific subsidiary, and subsequently locating the regulatory policies governing that parent organization within a specific geographic jurisdiction. A single vector search targeting the combined phrasing will frequently fail to bridge that connection, particularly if the necessary data points reside in separate documents. Naive RAG cannot decompose this prompt into sequential sub-questions, retrieve an intermediate answer, and use that insight to inform a secondary search.
Furthermore, the architecture exhibits high susceptibility to poor retrieval results. When the top search results are genuinely irrelevant to the user’s prompt, the large language model faces an impossible operational dilemma. It must either generate a response that ignores its grounding context—which inevitably triggers hallucinations—or output an honest but unhelpful statement indicating a lack of sufficient information. In high-stakes enterprise environments, neither outcome is acceptable.
Agentic RAG: Giving the System a Brain
Agentic RAG reframes the entire retrieval problem by shifting the role of the large language model. Instead of acting as a passive text generator that merely receives context and produces output, the model functions as an autonomous reasoning engine that actively orchestrates the entire retrieval lifecycle.
Where Naive RAG resembles a rigid pipeline, Agentic RAG operates as a dynamic loop centered on planning, execution, evaluation, and iteration. Returning to the library analogy, a dedicated research assistant does not simply grab the first few books off the shelf and begin writing. Instead, they read the initial sources, realize a critical piece of evidence is missing, consult a different database, cross-reference conflicting claims, and only begin drafting once they are confident in the sufficiency of their sources. Agentic RAG embeds this sophisticated behavioral pattern directly into the retrieval system.
The large language model is transformed from a consumer of static context into an active orchestrator. It decides what information to retrieve, where to locate it, whether the initial results meet quality standards, and how to proceed if they fall short. This shifts retrieval from a fixed preprocessing step into an adaptive, self-correcting process. While a naive system views retrieved context only once, an agentic system reasons continuously about the retrieval process itself, determining when to search, what terms to search for, and when enough information has been gathered to produce a reliable answer.
Four Mechanisms That Make RAG Agentic
The functional gap between a naive pipeline and an agentic system is defined by the integration of four distinct operational mechanisms. Each mechanism addresses a specific failure mode that linear retrieval cannot overcome on its own.
Query routing recognizes that different questions require entirely different data sources. A financial analysis query is best answered by querying a structured SQL database, whereas a corporate policy question demands semantic search across unstructured text documents, and a current events inquiry requires a live web search. Query routing grants the system the ability to decide where to search before executing the operation, examining the incoming query to select the appropriate tool or data source from a predefined registry. This prevents the common failure mode of forcing every distinct question through a single retrieval mechanism.
Query decomposition handles complex, multi-faceted prompts by breaking the original instruction into smaller, independently answerable components prior to executing any retrieval. Returning to corporate acquisition scenarios, the system avoids searching for a complex multi-part phrase as a single string. Instead, it first identifies the acquiring entity, retrieves that intermediate answer, and uses the result to construct a second, highly targeted query regarding regulatory obligations. Each answer informs the subsequent search, building toward a comprehensive response through a chain of precise retrievals.
Self-reflection and critique serve as the most consequential capabilities in the agentic toolkit. Following a retrieval operation, the system pauses to evaluate whether the retrieved chunks actually answer the question and whether they are relevant or merely contain noise. If the model determines the context is insufficient, contradictory, or off-target, it rewrites the query and initiates a new retrieval pass. This evaluation loop continues until the system reaches a satisfactory confidence threshold or hits a predefined iteration limit, preventing runaway loops while catching retrieval failures in real time.
Tool use and function calling expand the boundaries of what a retrieval system can accomplish. Through function calling, the large language model can invoke external tools mid-reasoning, such as an arithmetic calculator, a live web search application programming interface, a structured database executor, or a custom internal lookup tool. The model determines which utility is appropriate for each sub-task and invokes it within the same reasoning loop, combining retrieved text with live computation and structured data into a single coherent response.
Making the Choice: When to Use Which
Organizations evaluating these architectures face a fundamental trade-off between implementation cost and operational capability. Naive RAG involves a single embedding operation and one model call, resulting in low latency, predictable costs, and straightforward debugging. In contrast, Agentic RAG involves multiple reasoning steps, where each iteration adds latency and token consumption.
Industry guidance suggests choosing Naive RAG for applications with straightforward, factual lookups, well-structured document repositories, low latency requirements, and strict cost constraints. Conversely, Agentic RAG is recommended for use cases involving multi-hop reasoning across disparate documents, heterogeneous data sources requiring dynamic tool selection, complex synthesis tasks, and high-stakes enterprise environments where accuracy is paramount. Many production systems utilize a hybrid approach, routing high-volume, simple queries through a fast naive pipeline while reserving the agentic loop for complex or high-stakes inquiries.
The distinction between Naive RAG and Agentic RAG reflects a broader design pattern in modern technology: the choice between a rigid pipeline and an adaptive loop. For scenarios where a single, well-formed search reliably surfaces the correct answer, simpler architectures remain the optimal choice. For complex workflows involving multi-step reasoning and diverse data sources, the added complexity of an agentic system provides significant value for enterprise deployments.