


Amazon Web Services (AWS) has officially announced the general availability of AWS Glue 6.0, marking a significant milestone in the evolution of its fully managed, serverless data integration service. This latest version introduces a comprehensive suite of performance optimizations, updated runtime environments, and deeper integration with the Apache Iceberg ecosystem. Perhaps most notably for enterprise customers managing large-scale data workloads, AWS Glue 6.0 delivers a 30% price reduction compared to previous versions, reflecting a strategic effort to lower the barrier to entry for high-performance ETL (extract, transform, and load) processes.
At its core, AWS Glue 6.0 is built upon a modernized technical foundation designed to meet the increasing demands of modern data engineering teams. The service now runs on Apache Spark 4.1, Python 3.13, and Scala 2.13. By updating these core components, AWS is providing users with a faster, more efficient runtime engine capable of handling complex data transformations with greater speed and reliability. This upgrade is intended to streamline the developer experience, allowing teams to leverage the latest features of the Spark and Python ecosystems without the administrative overhead typically associated with managing underlying infrastructure.
Advancing Support for Apache Iceberg v3
A centerpiece of the AWS Glue 6.0 release is its industry-leading support for the Apache Iceberg v3 specification. As organizations increasingly adopt open table formats to manage massive data lakes, the ability to perform efficient, schema-flexible operations has become a top priority. AWS Glue 6.0 delivers the complete Iceberg v3 implementation, built on Iceberg 1.11.0, positioning itself as the most comprehensive serverless Spark service for this open-source standard.
The standout feature within this integration is the introduction of the VARIANT data type, complete with shredding support. In traditional data pipelines, handling semi-structured data—such as logs, event streams, and nested JSON—often necessitates cumbersome schema flattening, which can lead to data duplication, brittle pipelines, and significant performance bottlenecks. The VARIANT data type changes this dynamic by allowing developers to store and query semi-structured data directly without the need to flatten schemas or write complex, custom parsing code.
By utilizing VARIANT shredding, Glue 6.0 achieves superior query read performance compared to traditional string-based columns. Because the data is stored in a more structured, query-optimized format, systems can bypass the expensive overhead of repetitive parsing. This capability effectively eliminates the risk of pipeline breakage that often occurs when upstream data schemas evolve or change unexpectedly. For data engineers, this means less time spent on maintenance and debugging, and more time focused on delivering value from data.
Modernizing the Runtime for Scalability and Speed
Beyond the advancements in Iceberg support, AWS Glue 6.0 brings substantial improvements to the underlying Spark 4.1 engine. This upgrade is part of a broader commitment to ensuring that serverless ETL jobs remain performant as data volumes grow. The combination of the updated runtime and optimized engine performance enables real-time streaming capabilities with single-digit millisecond latency, a critical requirement for businesses operating in sectors like finance, cybersecurity, and real-time analytics.
The performance gains in Glue 6.0 are not merely incremental; they represent a fundamental shift in how AWS handles the execution of distributed jobs. By improving PySpark performance, the service helps reduce the execution time for resource-intensive data processing tasks. When coupled with the 30% cost reduction, organizations can expect a significantly improved price-to-performance ratio, allowing them to scale their data processing capabilities while maintaining or even reducing their overall cloud expenditure.
Integration and Deployment Workflow
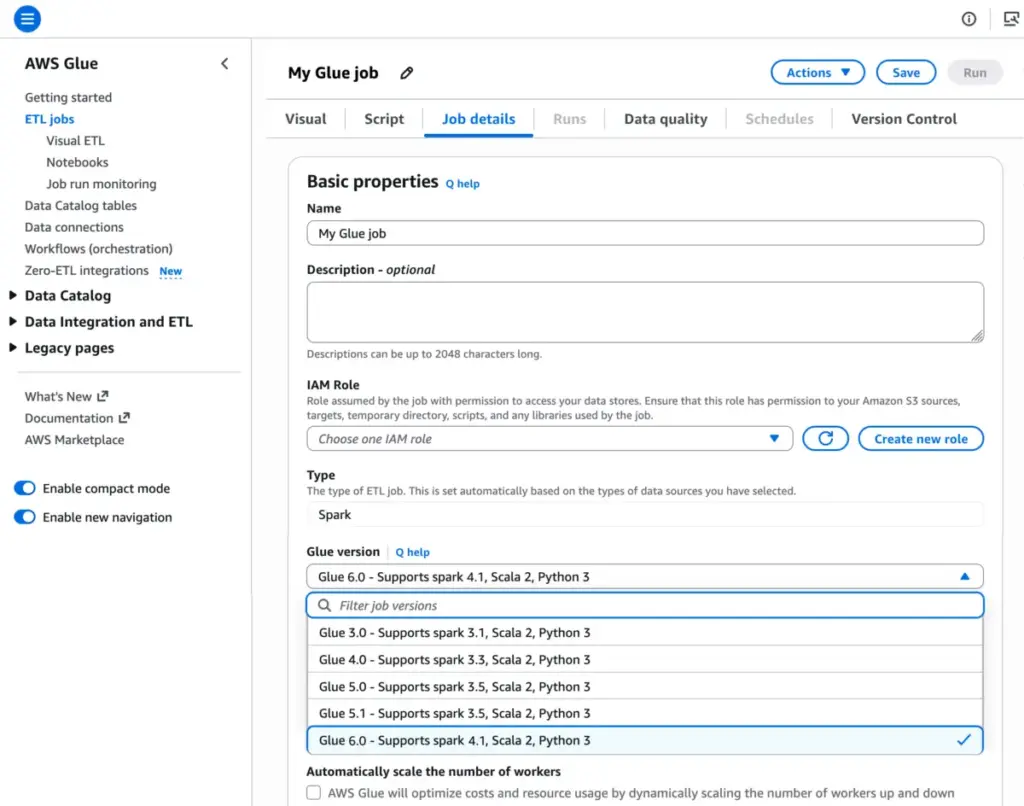
AWS has designed the transition to Glue 6.0 to be as seamless as possible, ensuring that existing investments in ETL jobs are protected. There are no API changes required to adopt the new version, meaning that teams can begin testing and migrating their workloads without refactoring their entire codebase. The version selection is handled via the --glue-version parameter, which is fully supported across the AWS Command Line Interface (AWS CLI), AWS SDKs, and the AWS Glue Studio environment.
For users who prefer a graphical interface, the AWS Glue Studio console provides a straightforward path to adoption. In the "Job Details" tab, users can simply select "Glue 6.0" from the version dropdown menu. This allows for both the creation of entirely new jobs and the migration of legacy jobs. To assist with the transition, AWS provides a sophisticated Spark upgrade agent within Glue Studio. This tool helps identify potential compatibility issues and suggests modifications, minimizing the manual effort typically required during major framework upgrades. Furthermore, for those looking to automate the process, the service includes an auto-upgrade feature that can facilitate the migration of existing jobs to the 6.0 runtime with minimal intervention.
For developers working in interactive environments, Glue 6.0 is fully integrated into AWS Glue Studio notebooks and Jupyter notebook sessions. By setting the %glue_version magic to 6.0, developers can immediately access the updated runtime and its associated features. This consistency across development, testing, and production environments is a hallmark of the Glue 6.0 release, ensuring that developers can benefit from the performance improvements at every stage of the data lifecycle.
Availability and Regional Support
AWS Glue 6.0 is available today across all AWS Regions where AWS Glue operates. This broad availability ensures that global enterprises can standardize their data pipelines on the latest version of the service regardless of where their data resides. AWS encourages customers to consult the "AWS Capabilities by Region" portal to verify specific regional deployment options and to stay informed about future roadmap updates.
The company has also introduced new tools for developers seeking technical assistance or documentation. The AWS MCP Server and various plugins for AI-driven development tools can now be used to query documentation, retrieve regional availability information, and troubleshoot issues related to the new Glue 6.0 features. These resources are designed to help teams quickly resolve questions and optimize their configurations without needing to navigate extensive static documentation manually.

Cost Structure and Economic Benefits
The economic model for AWS Glue 6.0 remains consistent with previous versions, emphasizing transparency and ease of use. Users are billed for the duration of their crawlers and ETL jobs, with costs calculated on a per-second, hourly rate basis. This serverless consumption model ensures that organizations only pay for the compute resources they consume during active processing.
The AWS Glue Data Catalog continues to operate under a simplified monthly pricing model. To support smaller workloads and development environments, the first million objects stored in the catalog are provided free of charge, as are the first million access requests. By maintaining this structure while simultaneously lowering the cost of the compute-heavy ETL jobs, AWS is signaling a strong commitment to supporting both small-scale projects and massive, petabyte-scale data lakes.
For organizations looking to delve deeper into the specifics of the migration, AWS has published comprehensive release notes and migration guides. These resources offer detailed insights into the differences between version 6.0 and its predecessors, providing a roadmap for teams to maximize the benefits of the new runtime and the Iceberg v3 features.
Feedback from the user community is a vital component of the AWS development process. AWS encourages developers to engage with the official AWS re:Post community for Glue to share their experiences, ask questions, and contribute to the ongoing improvement of the service. Whether through official support channels or community forums, the feedback loop remains a primary driver for the evolution of the platform. As teams begin to transition their workloads, the combination of lower costs and enhanced performance positions AWS Glue 6.0 as a critical tool for modern, data-driven organizations.